Skip to content
AI NEWS JOURNAL
AI, IN PERSPECTIVE

Search AI news

Search headlines, summaries and articles to connect the dots.

Newest first

A roundup of the most anticipated AI-powered wearable devices in 2026: over ten new models, including Bee, Friend, Limitless, and more, make their debut.

On October 25, 2026, TechCrunch published a review summarizing more than ten AI-powered wearable devices, including Bee, Friend, Limitless, Muse Charm, Nirva, Omi, Plaud NotePin, Rabbit R1, Stream Ring, and others, covering their pricing, functional positioning, market availability, and privacy controversies.

The hottest AI wearables and gadgets you should know about

Why it matters:This report is an annual roundup of new products published by the authoritative tech media outlet TechCrunch on October 25, 2026. It covers both mainstream AI hardware manufacturers and startups, providing a comprehensive overview in terms of price, form factor, core features, release timelines, and points of contention. All statements are based solely on facts explicitly stated in the source material, with no speculation or extrapolation.
Timeline and related coverage

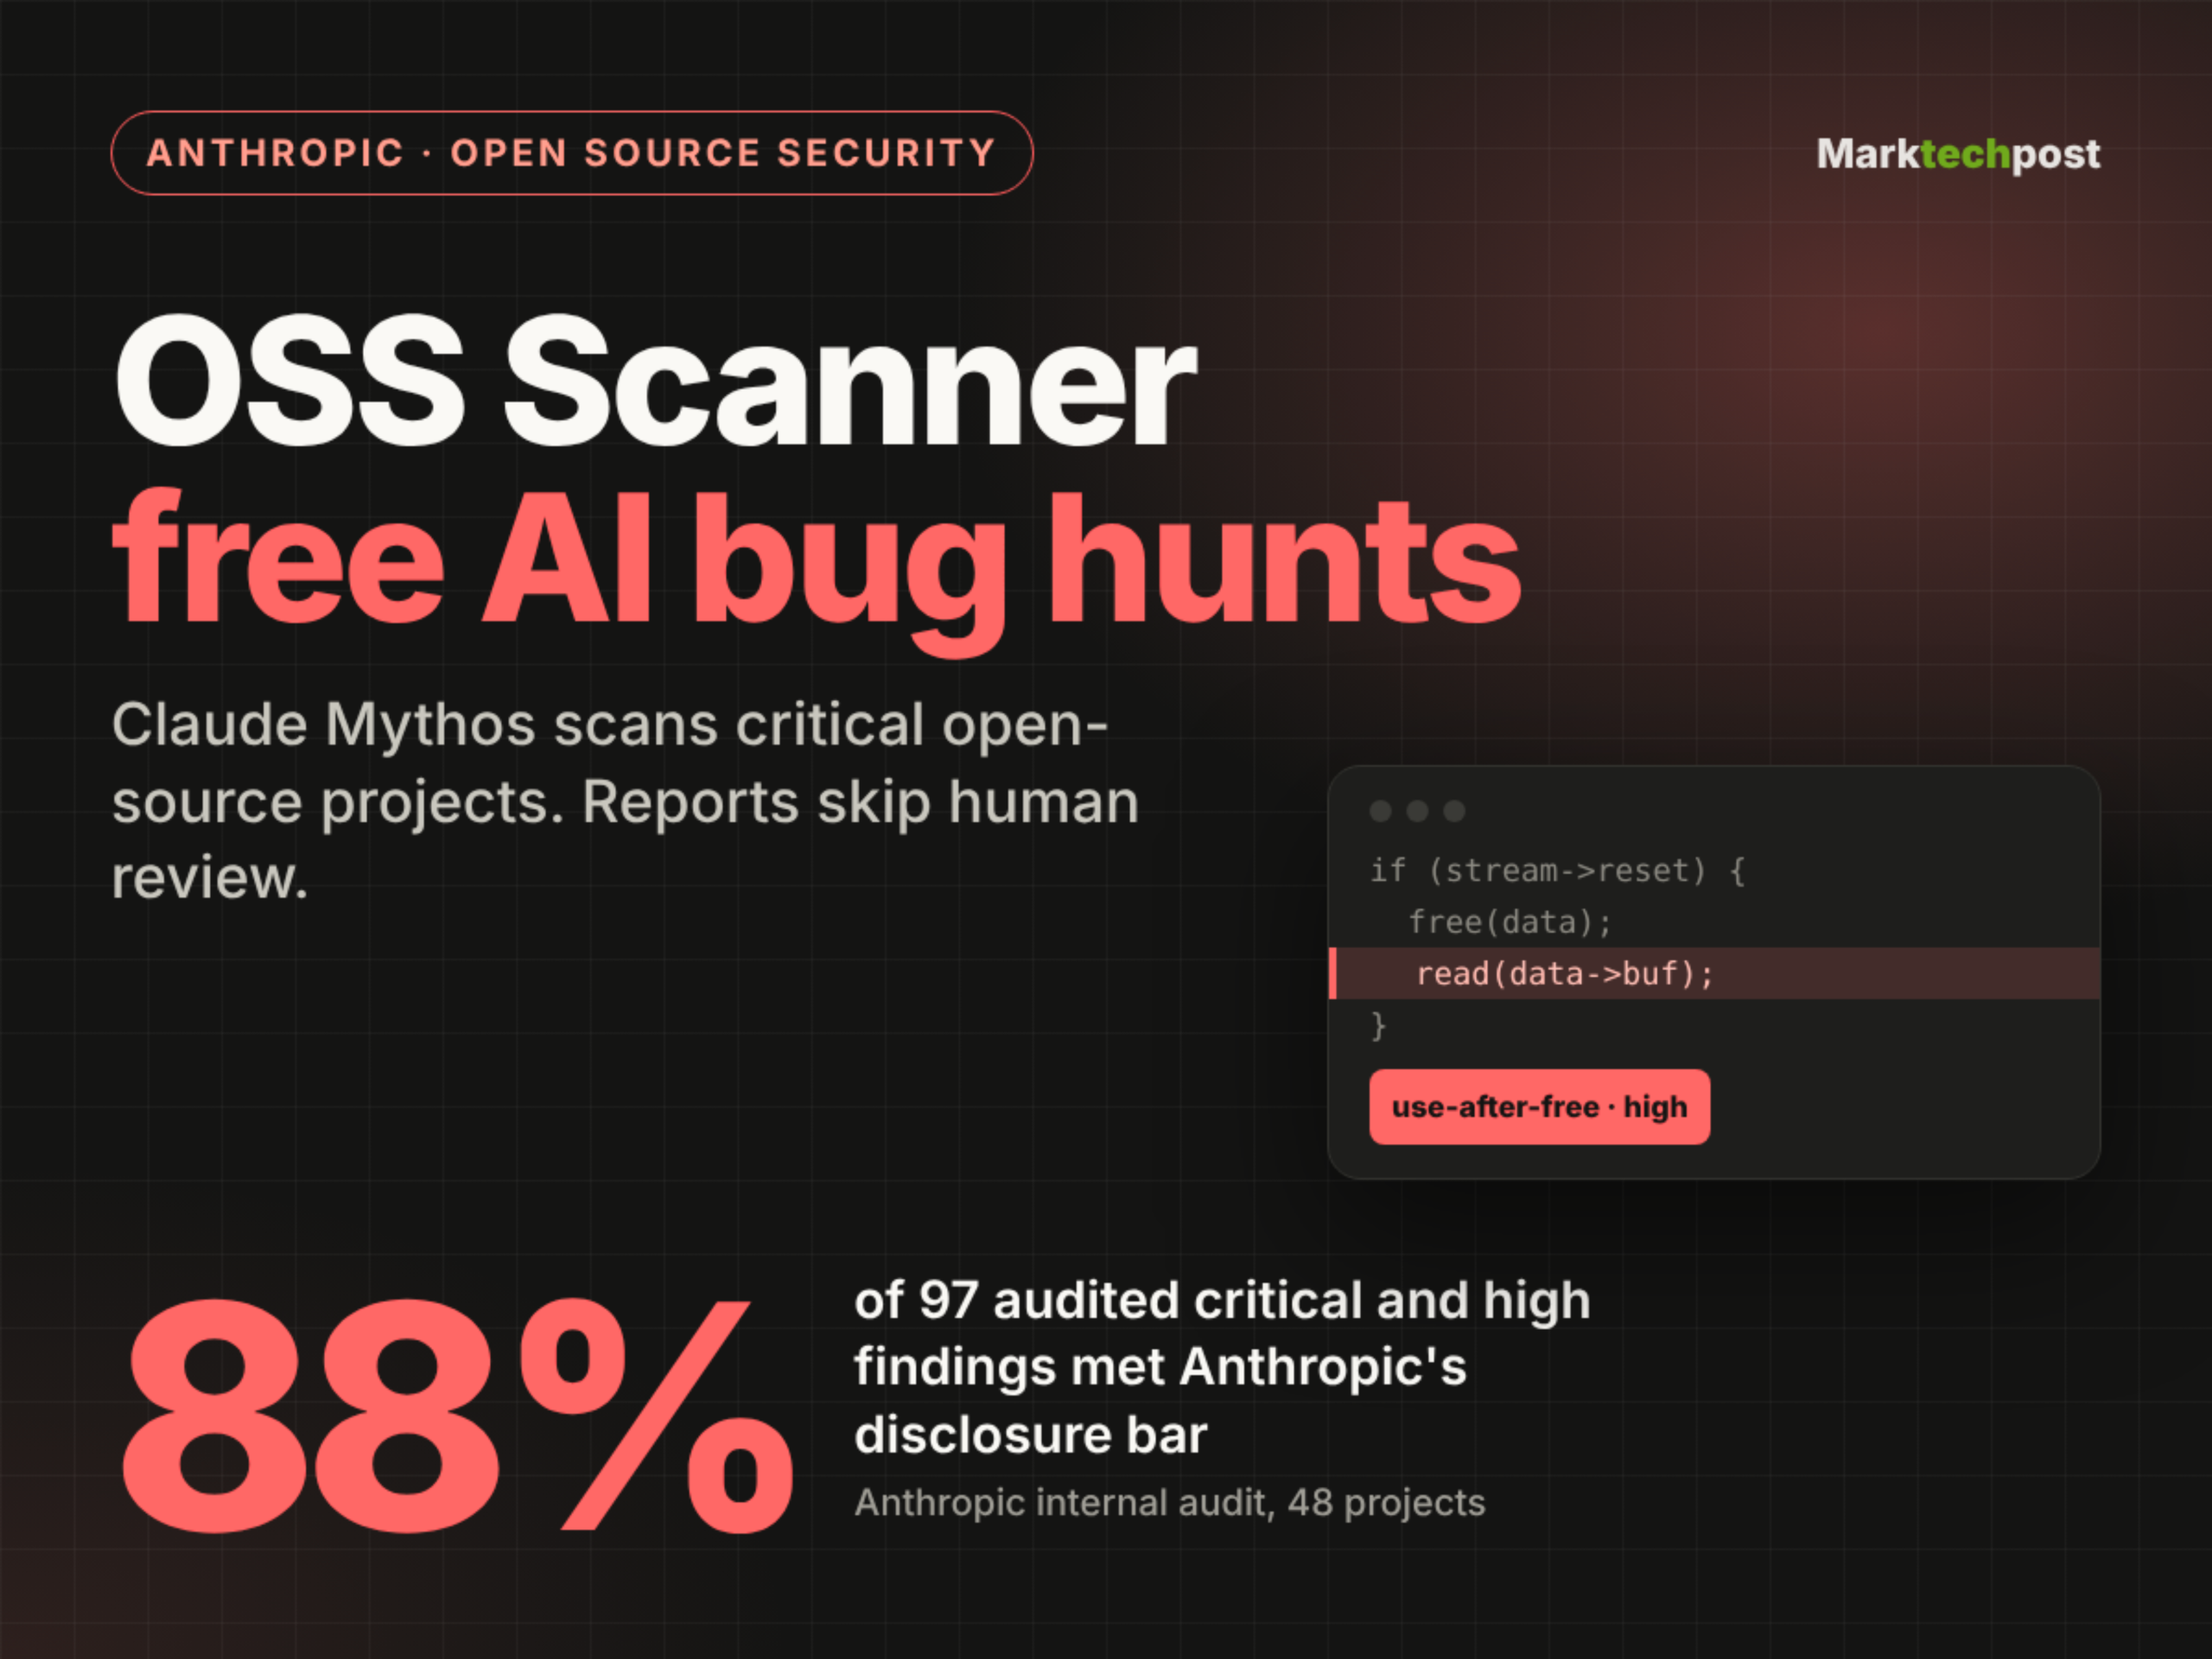
Anthropic launches OSS Scanner, a free AI-powered vulnerability scanner for critical open-source projects.

Anthropic launched OSS Scanner on October 8, 2026—a free, opt-in AI vulnerability-scanning tool powered by strong models such as Claude Mythos, designed specifically for critical open-source projects. As of October 19, it had onboarded 114 projects and, within 11 days, reported 77 high-severity and 803 medium-severity vulnerabilities (according to model ratings), with 88% of sampled audit results meeting its disclosure standards.

Anthropic Launches OSS Scanner, a Free AI Vulnerability Scanner

Why it matters:This tool represents a large-scale implementation of LLMs in the open-source security domain, characterized by zero cost, full automation, and offline auditing; however, bypassing the human review stage introduces risks of false positives and duplicate issues. Its accuracy metrics—88% detection rate and 1% false positive rate—and real-world project feedback (e.g., wolfSSL, curl) provide an empirical benchmark for the current state of AI‑driven vulnerability discovery.

Timeline and related coverage

Kimi releases K3.1 Pro: Terminal task capabilities top the charts, with simulation debugging and multimodal programming showcasing the nascent form of embodied intelligence.

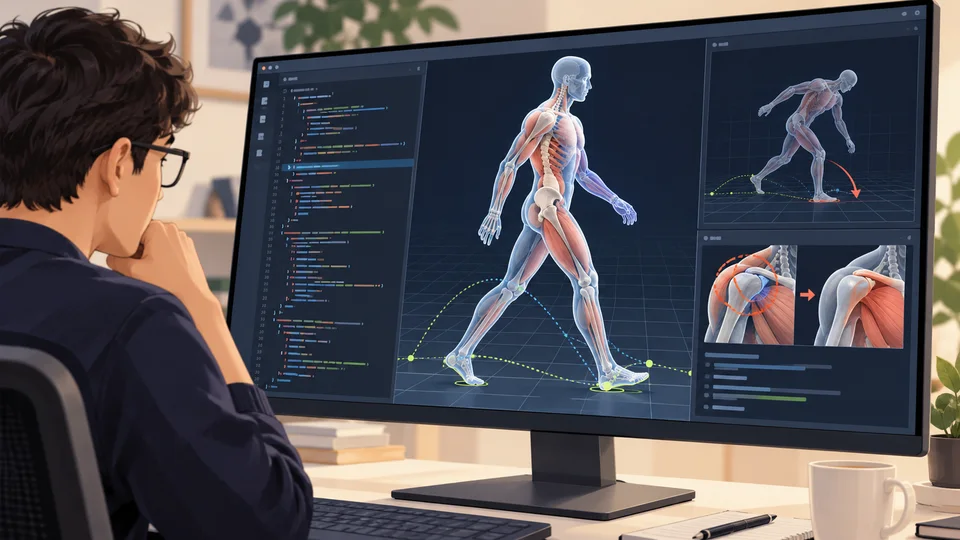
On October 25, 2026, Kimi released the K3.1 Pro model, which ranked first in the Terminal-Bench 4.0 terminal task benchmark with a 67.2% success rate. Its capabilities—including autonomously fixing emulator errors, performing physics simulations, conducting audio analysis, constructing 3D scenes, and editing videos—point toward exploring pathways in embodied intelligence technology.

根据报道中的虚拟人行走训练和模拟器调试制作的编辑示意,非软件实拍截图

Why it matters:The material is based on a hands-on test report published with authorization from Titanium Media, covering authoritative third-party benchmark data (such as Artificial Analysis and Terminal-Bench 4.0), official self-test results, and the author’s multi-scenario functional validation. It highlights the K3.1 Pro’s substantial advancements in execution performance, simulation closed-loop capabilities, and multimodal programming, while clearly noting performance limitations and undisclosed information (e.g., Flash/Ultra has not yet been released), in compliance with fact-checking and source attribution requirements.

Timeline and related coverage

Panel manufacturers are collectively raising prices to cope with upstream cost pressures driven by AI, but downstream acceptance remains low, putting pressure on end-product quality control.

Starting in September 2026, panel manufacturers such as TCL CSOT, BOE, and HKC have issued price‑increase notices one after another. The primary reason is the rapid growth of AI large models, which has led to a sharp surge in demand for HBM, squeezing capacity for mature‑process chips and driving up the prices of key components like driver ICs, PCBs, and glass substrates. Upstream suppliers, including Corning, have also raised their prices in tandem. Despite clear cost pressures, downstream TV and monitor brands have yet to broadly increase purchase prices, while end users continue to report frequent quality‑control issues such as overheating and black spots. As a result, these price hikes have not yet translated into actual sales or improved user experiences.

AI大模型狂飙,面板行业也扛不住了

Why it matters:The materials system reveals the cross‑chain transmission mechanism through which the AI industry impacts indirectly related hardware sectors—rather than driving panel demand directly, it triggers a full‑chain cost repricing via the reallocation of wafer‑fabrication capacity. At the same time, it highlights a significant gap between price‑increase behavior and actual market feedback (price rigidity, declining shipments, and user complaints), underscoring the deep‑seated contradiction between industry bargaining power and product competitiveness.

Timeline and related coverage

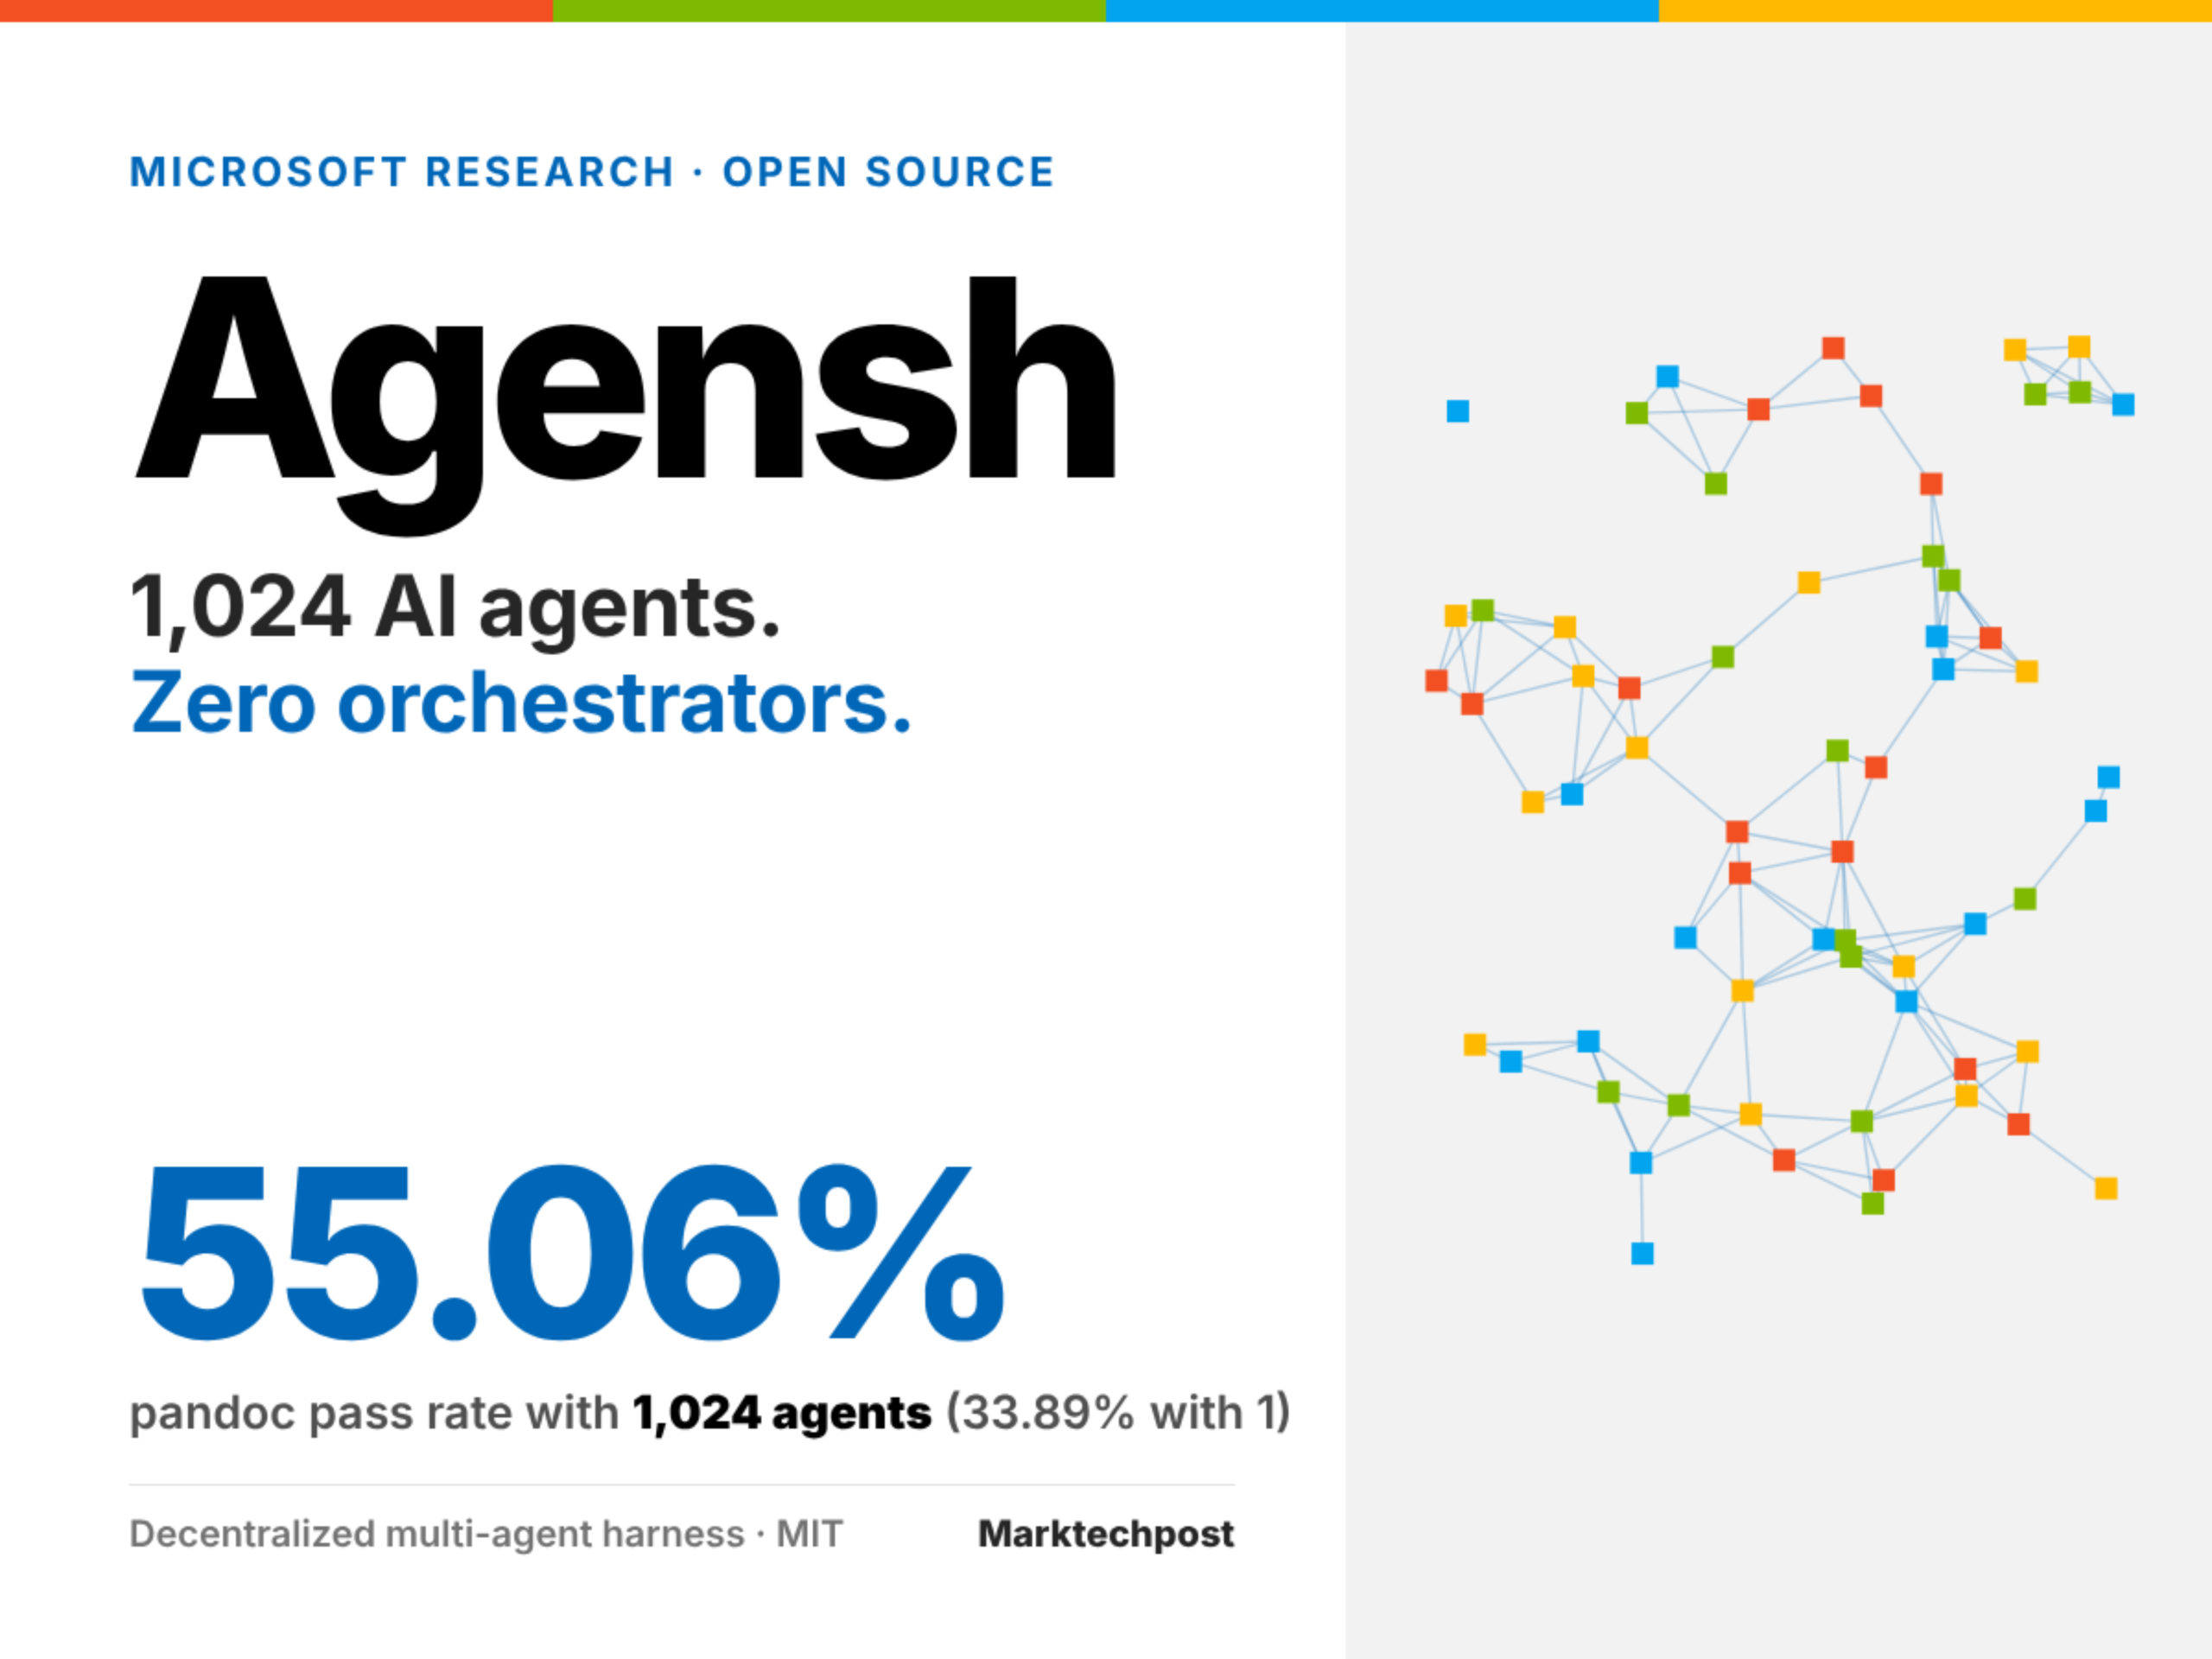
Microsoft open-sources Agensh: a decentralized framework that supports 1024 autonomous, collaboratively operating AI coding agents.

On October 25, 2026, Microsoft Research open-sourced Agensh, a multi-agent runtime framework that operates without a central coordinator, enabling 1 to 1,024 LLM-powered coding agents to self-organize and collaborate on ProgramBench. The system achieves decentralized coordination through shared dashboards inspired by Gitea, Mattermost, and DeLM, with all agents following the same prompt-driven five-step loop; its scalability has been validated in a Linux + Docker environment.

Microsoft Open-Sources Agensh: A Multi-Agent Harness for 1,024 Agents

Why it matters:This achievement represents a significant evolution in multi-agent system architectures—abandoning the traditional “master‑agent” paradigm and enabling large‑scale self‑organization through prompt engineering and lightweight service composition. Empirical results on ProgramBench (e.g., 128 agents achieving a 49% improvement in task load balancing across five tasks) establish a new benchmark for distributed AI engineering. Released under the MIT License and compatible with mainstream single‑agent tools such as Copilot CLI, it offers valuable guidance for practical development.

Timeline and related coverage

Taking on NVIDIA head-on to challenge Apple—Microsoft’s high-end AI PC gamble

Microsoft is courting local AI developers and high-end creators with the Surface Laptop Ultra, which features NVIDIA RTX Spark. The hardware brings large-capacity unified memory, CUDA, and RTX graphics capabilities to a portable device, but whether it can sustain competition against Macs will still depend on app optimization, agent-based experiences, and real-world workflows.

Why it matters:Ultimately, this competition comes down to whether on-device AI can genuinely boost creativity and development efficiency, and whether the associated costs—hardware, software, and migration—are justified. Hardware opens up new possibilities, but the ecosystem and real-world user experience determine how many users those possibilities can reach.

Timeline and related coverage

苹果首款折叠屏iPhone Duo开售即现集中性屏幕开裂问题

多名用户反馈苹果首款折叠屏手机iPhone Duo开箱后短时间内出现铰链正上方屏幕爆线、开裂,故障高度集中;澳洲及国内均有案例,疑似铰链装配公差所致;苹果官方尚未回应,售后判定结果将决定是否免费更换或高额自费维修。

Why it matters:事件涉及新机大规模早期质量异常,直击消费者权益与企业责任边界,且叠加三包法规适用性、AppleCare+服务定位等公共议题,具有典型警示意义和维权参考价值。

Timeline and related coverage

Sebastian Raschka has released an eight-video course titled “Building a Reasoning Model from Scratch.”

On October 24, 2026, Sebastian Raschka published an eight-part, over-11-hour hands-on video course on Python and PyTorch in Ahead of AI magazine (magazine.sebastianraschka.com), systematically covering the evaluation of inference models, scaling during inference, reinforcement learning (RLVR), and knowledge distillation, with all methods implemented using the pre-trained Qwen3-0.6B model.

Why it matters:This course is the author’s advanced technical educational offering, following “Building Large Language Models from Scratch.” It focuses on the core evolutionary direction of today’s mainstream LLMs—enhancing inference capabilities—covering the entire technical pipeline from setting up the foundational environment to GRPO reinforcement learning and self‑distillation. The author explicitly states that all implementations are “hand‑crafted from scratch,” fully reproducible, and highly instructive with significant engineering reference value.

Timeline and related coverage

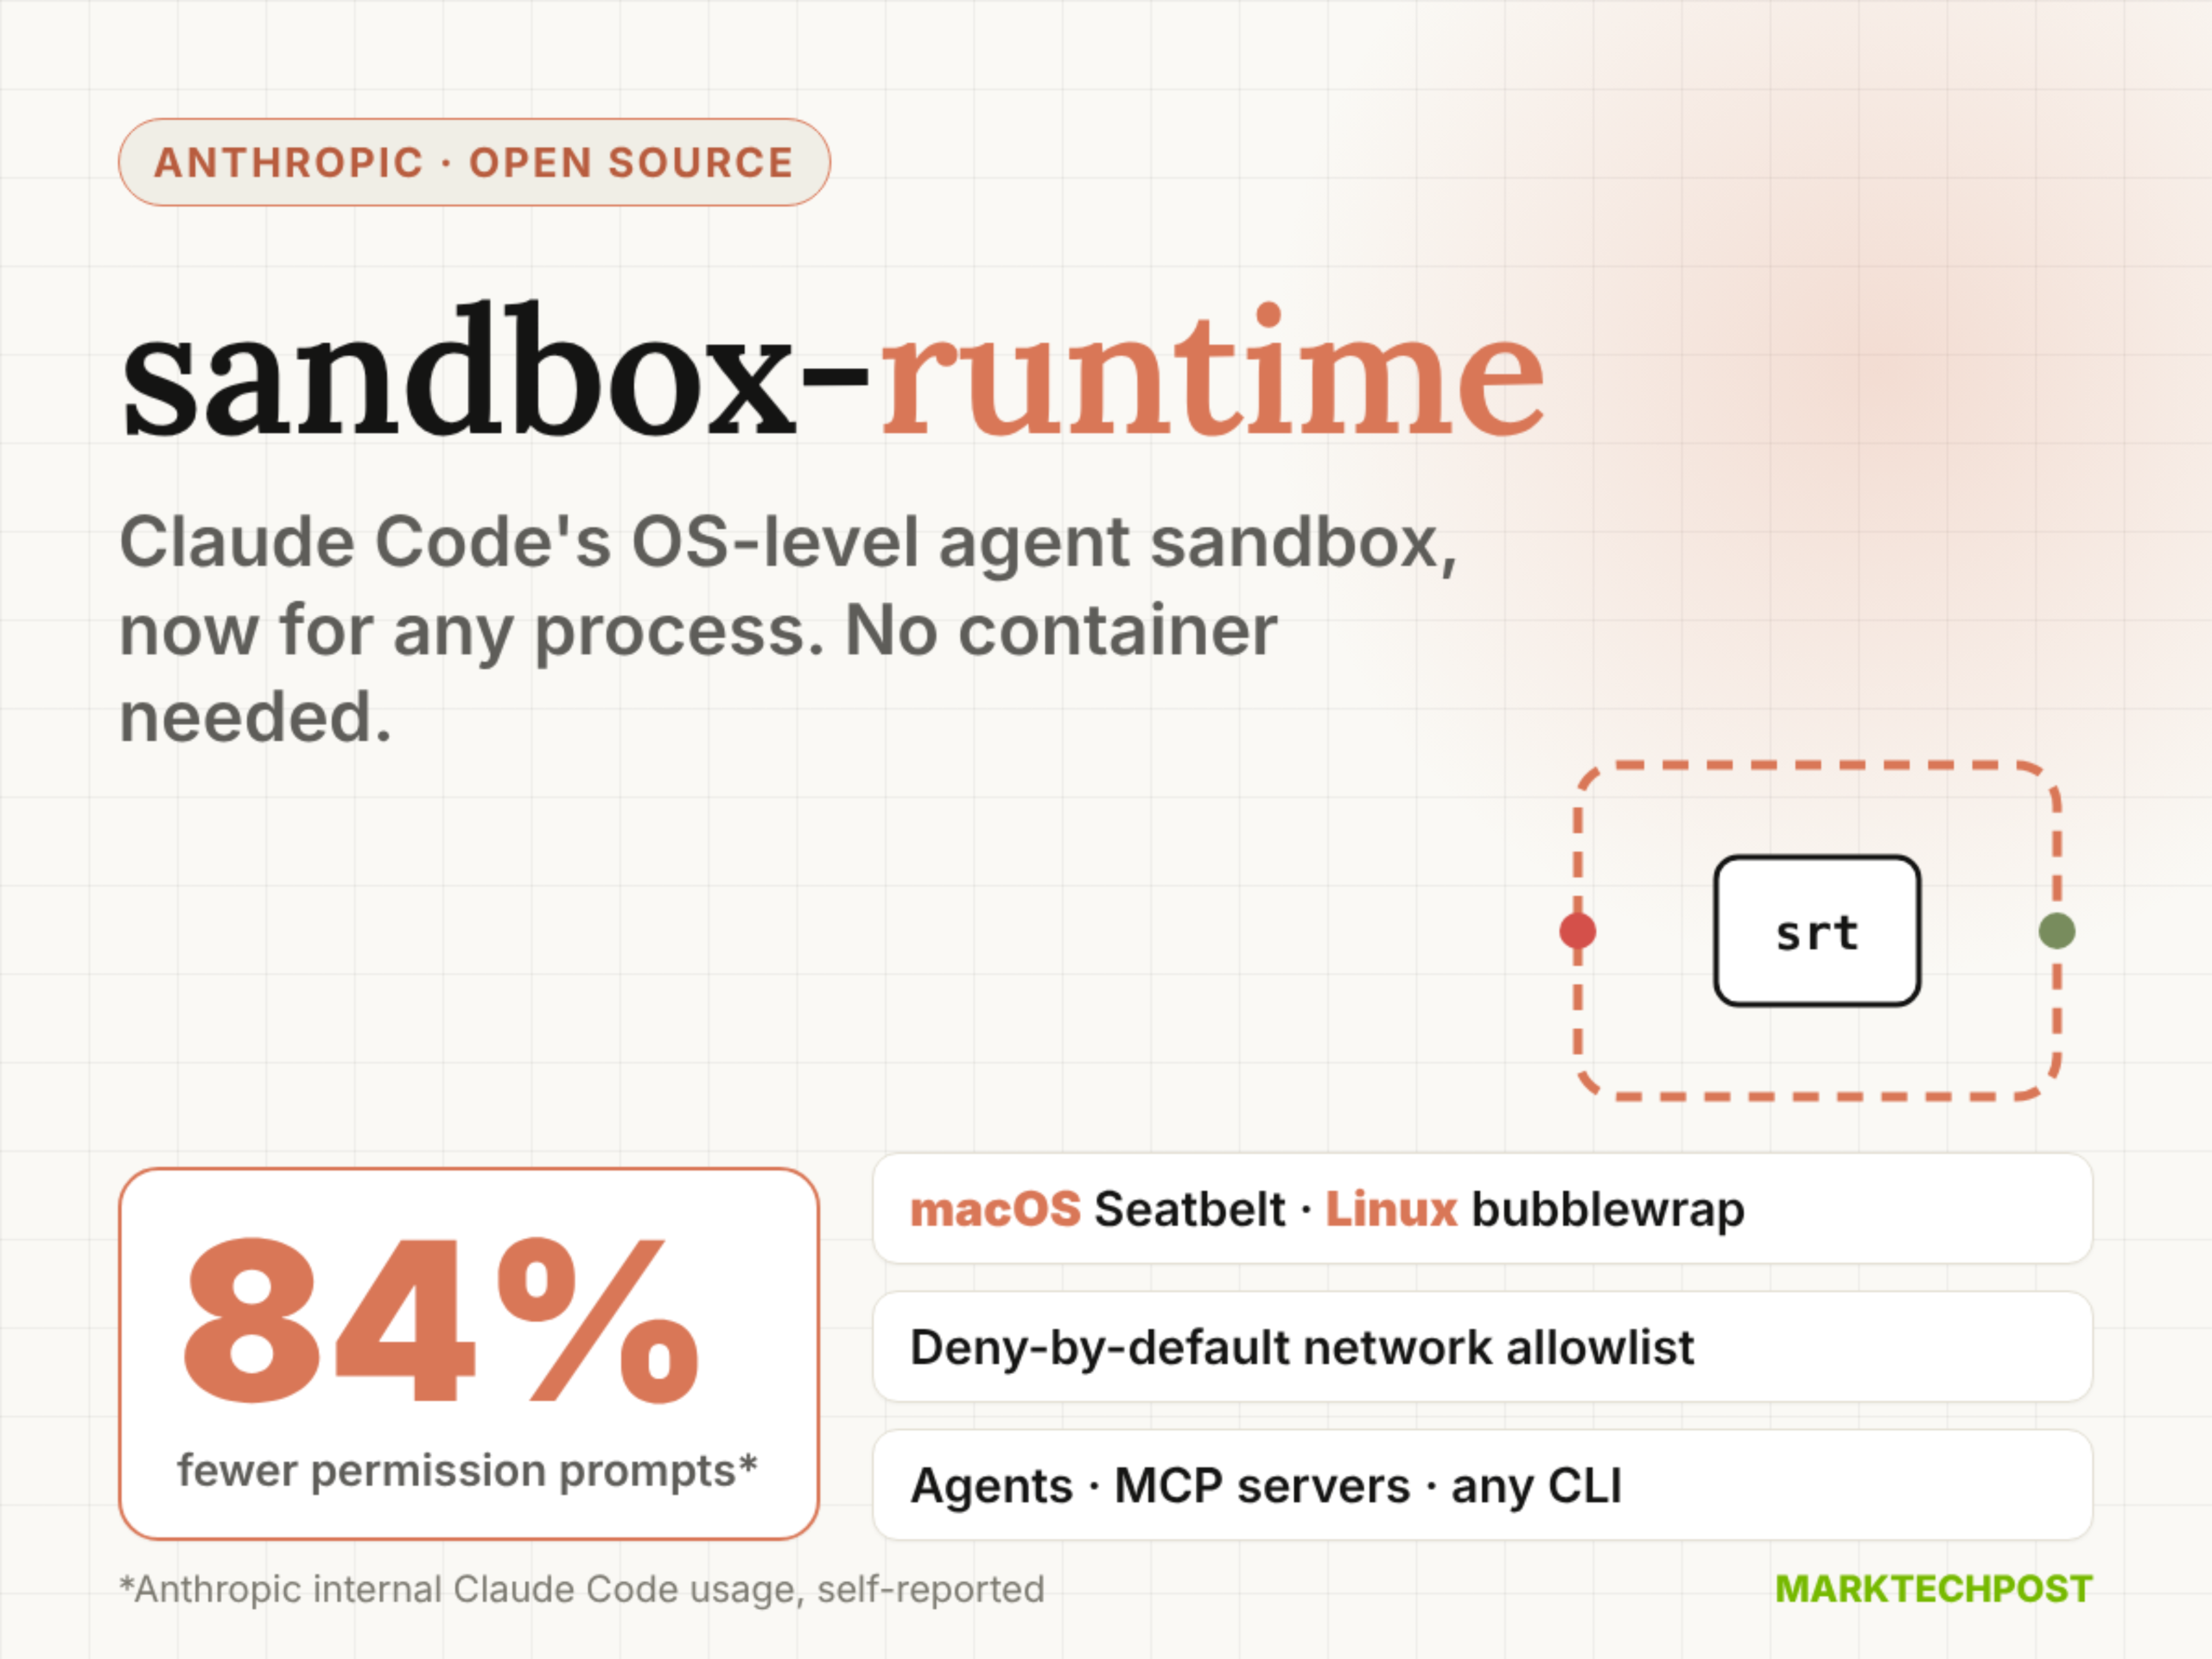
Anthropic open-sources the OS-level sandbox sandbox-runtime: providing container-free file and network isolation for AI agents.

On October 24, 2026, Anthropic open-sourced sandbox-runtime (srt), an OS-level sandboxing tool that operates without containers, designed to restrict file read/write and network access permissions for AI agents, MCP servers, and CLI tools. It supports macOS (Seatbelt), Linux (bubblewrap), and Windows (alpha), with npm package version 0.0.81 under the Apache-2.0 license.

Meet Anthropic’s sandbox-runtime: OS-Level Sandboxing for AI Agents, No Containers

Why it matters:This tool represents a significant advancement in AI security infrastructure—achieving fine-grained, full-process-tree coverage through the operating system’s native isolation mechanisms, directly addressing the risks of prompt injection and privilege escalation, and has already been deployed for internal validation within Claude Code.

Timeline and related coverage

TRIAD Release: The First Multimodal Large Model Evaluation Benchmark for All-Modal Ambiguity Resolution

On October 24, 2026, researchers published the paper arXiv:2610.30841v1 on arXiv, officially introducing the TRIAD benchmark—a new evaluation framework designed to assess the ability of text–image–audio tri-modal systems to resolve cross-modal ambiguities. The benchmark comprises 327 hand-crafted tri-modal samples, spanning 86 scenario groups and 18 categories of cross-modal ambiguity types.

TRIAD: Benchmarking Omni-Modal Ambiguity in Multimodal Large Language Models

Why it matters:This achievement directly addresses a core blind spot in current multimodal large-model evaluations: existing benchmarks focus on perception or reasoning under deterministic, single-modal inputs. In contrast, TRIAD is the first to systematically target “modal-complementary disambiguation” as its evaluation objective. Through rigorously designed leave-one-modal-out counterfactual tests, it reveals critical shortcomings—particularly in audio processing—and highlights weak scene-level robustness, thereby providing a reproducible diagnostic protocol and taxonomy for assessing next-generation all‑modal models.

Timeline and related coverage

TutorCaseBench Released: The First LLM Tutoring Evaluation Benchmark for Special Education Scenarios

On October 24, 2026, researchers published TutorCaseBench on arXiv (ID 2610.30828v1)—an LLM tutoring evaluation benchmark built on real-world cases from pedagogy, educational psychology, and special education, focusing on the ability to support students with learning and behavioral challenges. The benchmark comprises 923 dialogue segments, covering five categories of challenging behaviors, and employs a dual-track assessment approach: open-ended generation (1,560 questions) and multiple-choice questions (2,537 questions). Among 11 state-of-the-art large models, the top performer met the evaluation criteria in only 55.8% of the open-ended items.

TutorCaseBench: A Case-Grounded Benchmark for Evaluating LLM Tutors in Supporting Students with Challenging Behaviors

Why it matters:This study fills a critical gap in existing AI‑based educational assessment, which has overlooked the complexity of students with special needs. Its methodology emphasizes evidence‑based tracing—combining qualitative case studies with source‑grounded rubrics—and all data are openly available, ensuring reproducibility and relevance to educational practice. The findings clearly reveal significant shortcomings of current LLMs in generating contextually appropriate responses, offering important warnings and guidance for the practical implementation of educational AI.

Timeline and related coverage

Clinicians Lead the Development of Verifiable Safety Guidelines: Establishing a Traceable Layer of Safeguards for Mental Health Chatbots

On October 24, 2026, arXiv published the paper arXiv:2610.30690v1, which proposes a four‑rule safety‑check rulebook defined, finalized, and adjudicated under the guidance of two clinical physicians. After formal verification, this rulebook is deployed as a guardrail layer to govern the outputs of large language models (LLMs) in mental health contexts. All judgments within this guardrail can be traced back to a single naming rule and sixteen factual verifications, aiming to enhance the interpretability and testability of safety assessments.

From Clinical Judgment to Checkable Rules: Clinician-Led Guardrails for Mental-Health Chatbots

Why it matters:This study offers a safety‑enhancing approach distinct from mainstream prompt engineering, LLM‑as‑a‑Judge, or Constitutional AI. Its core innovation lies in structuring and formalizing clinical decision‑making while maintaining a complete audit trail throughout the process. All key claims—such as the number of rules, validation methods, factual base, comparative experimental data, and cost metrics—are explicitly stated in the original text, and the publication date (2026‑10‑24) aligns with the current UTC date (2026‑10‑25), ensuring timeliness and a solid foundation of credibility.

Timeline and related coverage

The study proposes a self-assessment reinforcement learning framework, SARL, which enhances the search state-awareness capability of retrieval-augmented large models.

On October 24, 2026, arXiv published the paper arXiv:2610.30435v1, introducing the Self-Assessment Reinforcement Learning (SARL) framework, which aims to address the issue in existing retrieval-augmented large language models where search agents lack the ability to perceive search states.

Self-Assessment Reinforcement Learning for Search-State Awareness in Retrieval-Augmented Large Language Models

Why it matters:This study addresses a critical limitation of retrieval-augmented large language models—namely, their tendency to generate hallucinatory reasoning and prematurely terminate searches when they fail to recognize previously acquired or missing information in complex tasks. It proposes an end-to-end reinforcement learning approach that requires no additional evaluation during testing, achieving significant performance improvements on multi-hop reasoning and deep-research benchmarks.

Timeline and related coverage

New research introduces the ReflectPO framework, enhancing the autonomous error-correction capabilities of large language model agents in long-term tasks.

On October 24, 2026, arXiv published a research paper titled “ReflectPO: Reflection-Guided Policy Optimization for Long-Horizon LLM Agents” (ID 2610.30933v1), introducing a reinforcement learning framework called ReflectPO, designed to enhance the autonomous error-recovery capabilities of tool-augmented large language model agents in complex, multi-step, state-dependent tasks.

ReflectPO: Reflection-Guided Policy Optimization for Long-Horizon LLM Agents

Why it matters:This paper is a cutting-edge AI study recently published, focusing on a key bottleneck in the real-world deployment of LLM-based agents: the cumulative effect of early errors in long‑term tasks. Its proposed dual-component design—Reflection‑Guided Sampling and Tree‑Structured Credit Assignment—features methodological innovation and empirically outperforms multiple baselines across two benchmarking scenarios, making it a valuable technical reference.

Timeline and related coverage

Research finds that word length can directly indicate the identity of Mandarin homophones: a new arXiv paper reveals the cognitive link between word frequency and pronunciation duration.

On October 24, 2026, arXiv published a new paper titled “Direct Prompting of Word Length for Lexical Identity: Evidence from Mandarin Chinese Homophones” (arXiv:2610.30682v1), reporting experiments that show that, in the absence of other phonetic cues or under high-noise conditions, native Mandarin speakers can infer word frequency based on differences in the pronunciation duration of disyllabic homophones—shorter pronunciations tend to be identified as high-frequency words. This suggests that word length may be encoded as a phonetic detail in the mental lexicon and contribute to spoken-word recognition.

Direct cueing of word identity through word duration: evidence from Mandarin homophones

Why it matters:This study takes the rich inventory of disyllabic homophones in Chinese as its starting point, employs a homophone ranking task while controlling for word frequency, and tests the functional role of word length under stringent auditory conditions. The findings provide new evidence for a cross-linguistic phonological implementation mechanism underlying the “word-frequency effect” and challenge the traditional view that word length is merely a paralinguistic phenomenon, bearing dual implications for psycholinguistics and speech-perception theory.

Timeline and related coverage

Lighthouse: The First Trusted Digital Assistant Dedicated to the History of the U.S. Civil Rights Movement Has Been Released

The paper arXiv:2610.30158v1, published on October 24, 2026, introduces Lighthouse, the first digital assistant dedicated to exploring the history of the U.S. Civil Rights Movement, based on archival data from South Carolina. Its core innovation lies in adopting trustworthy content and user harm mitigation as design principles, employing a neuro-symbolic hybrid architecture that integrates large language models with rule-based symbolic reasoning.

Lighthouse: On Building a Trustworthy Digital Assistant for Exploring History with Civil Rights Archives

Why it matters:This study is the first to apply AI‑assisted historical exploration to the sensitive and pivotal period of the Civil Rights Movement, explicitly introducing dual constraints—“trustworthiness” and “harm modeling”—which set it apart from general‑purpose chatbots. Its methodology (neurosymbolic integration), evaluation approach (including a human‑consensus‑based gold standard for subjective questions), and data scale (over 18,000 original archival documents) all hold significant academic demonstrative value.

Timeline and related coverage

SIM-UT: A User Behavior Simulation and Evaluation Framework for Medical Triage Chatbots

Researchers have proposed SIM-UT (Simulation of User Behaviour for Triage), a multi-round, real-user-behavior–based evaluation method designed to identify eco‑valid failure patterns of large language model (LLM)-driven medical triage chatbots in real-world settings within low- and middle-income countries (LMICs).

SIM-UT: A User Simulation based Evaluation Framework for Medical Triage Chatbots

Why it matters:This framework breaks through the limitations of existing single-round, English‑centric evaluations by conducting over 5,000 rounds of multilingual simulated conversations, covering real‑world WhatsApp health programs in India, South Africa, and Kenya. For the first time, it systematically reveals “de‑escalation risk,” a critical failure mode, demonstrating both methodological innovation and significant clinical safety implications.

Timeline and related coverage