
05:07
TODAY’S BRIEFING
进入资讯流 今日要闻

01 / IN FOCUS
数据中心扩张引发全美地方反对,成为2026年中期选举关键议题
The Verge · AI
02 / IN FOCUS
vLLM 语义路由器发布 d3-ultra:一款 270 亿参数的开源多模态决策模型
MarkTechPost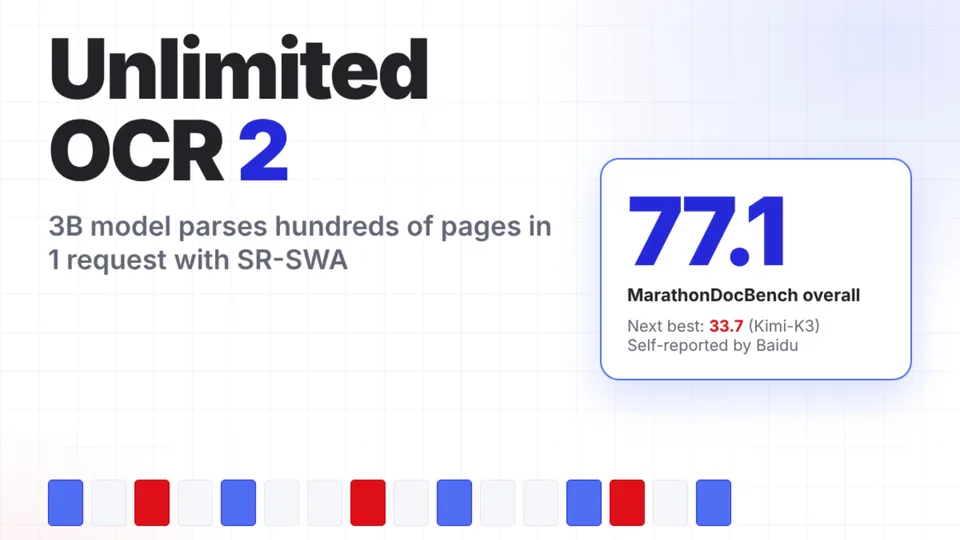
03 / IN FOCUS
百度开源无限OCR 2,用于百页文档解析
MarkTechPost研究与技术 / 04雅可比透镜的数学理论arXiv cs.LG
04 / IN FOCUS
雅可比透镜的数学理论
arXiv cs.LGAI 内容创作 / 05TraceQuery:从扩散语言模型的完整去噪轨迹中学习哪些部分需要重新计算arXiv cs.CL
05 / IN FOCUS
TraceQuery:从扩散语言模型的完整去噪轨迹中学习哪些部分需要重新计算
arXiv cs.CL研究与技术 / 06明智地低语:用于ASR微调的智能子集选择arXiv cs.CL
06 / IN FOCUS
明智地低语:用于ASR微调的智能子集选择
arXiv cs.CL研究与技术 / 07OpenESM:能量引导模型具有可扩展性,是基础学习者arXiv cs.CL
07 / IN FOCUS
OpenESM:能量引导模型具有可扩展性,是基础学习者
arXiv cs.CL研究与技术 / 08EKT路由器:面向具身视觉-语言模型的专家证据对齐arXiv cs.CV
08 / IN FOCUS
EKT路由器:面向具身视觉-语言模型的专家证据对齐
arXiv cs.CV模型动态 / 09Nemotron 3.5 Bolt 74B-A9B 24GB:一种用于本地人工智能的视觉-语言混合模型arXiv cs.CV
09 / IN FOCUS
Nemotron 3.5 Bolt 74B-A9B 24GB:一种用于本地人工智能的视觉-语言混合模型
arXiv cs.CVAI NEWS × FOXAI从信号发现下一步
探索 AI 工具 从发现前沿资讯,到找到趁手的工具。
发现好用的 AI
左右滑动探索 →C Claude通用助手与搜索
 Gemini通用助手与搜索
 Midjourney图像生成与编辑
 Krea图像生成与编辑
 Runway视频与动画
 Suno音乐与音频
 ElevenLabs语音与转写
 Notion AI办公与效率
 Gamma办公与效率
 Cursor编程与开发
Claude通用助手与搜索Claude 是 Anthropic 推出的 AI 助手,可通过对话协助写作、阅读资料、分析数据和编程,并将部分任务整理为可继续编辑的文档、表格或演示文件。适合希望把想法、资料和初稿衔接起来的个人与团队。
GGemini通用助手与搜索Gemini 是 Google 的 AI 助手,可通过对话协助写作、规划、整理资料和分析上传文件,也可用 Deep Research 围绕一个主题检索资料并生成研究报告。
MMidjourney图像生成与编辑Midjourney 是从文字和参考图片生成视觉作品的 AI 创作工具。可在网页 Create 页面输入提示,比较生成版本,再使用变体、编辑、放大或图像转视频等功能继续创作。
KKrea图像生成与编辑Krea 是 AI 视觉创作工作空间,可从文字或参考图生成图片,比较不同模型与变体,再进行编辑、细节增强和放大,也提供视频及其他创意工具入口。
RRunway视频与动画Runway 是集视频生成、视觉编辑和创作流程于一体的 AI 平台。可从文字、图片或已有片段开始,生成或修改镜头,再进行延长、放大和导出,服务于概念短片、广告及其他视觉制作。
SSuno音乐与音频Suno 是通过文字描述、歌词和参考素材创作歌曲的 AI 音乐平台。用户可生成带人声的歌曲或音乐,再使用编辑、重混与音轨分离等功能继续制作和分享。
EElevenLabs语音与转写ElevenLabs 是提供 AI 语音生成、音频创作和语音智能体的平台。创作者可以制作配音、有声书、播客及本地化内容,开发者则可通过 API 接入语音生成、转录和对话能力。
NNotion AI办公与效率Notion AI 是集成在 Notion 工作空间中的 AI 助手,用于查找团队知识、生成和编辑页面、处理数据库及整理会议内容。它结合工作空间和已连接应用的上下文,帮助把资料查询、内容整理和后续任务放在同一工作环境中完成。
GGamma办公与效率Gamma 是用 AI 协助制作演示文稿、文档、网页和视觉内容的产品,可从目标、提纲或已有资料开始生成内容,再通过对话、布局与自由编辑调整成品。
CCursor编程与开发Cursor 是围绕软件开发任务工作的 AI 编程产品,可在代码上下文中协助规划、修改、测试和审查代码,并提供桌面、命令行及云端智能体等使用方式。
AI 正在发生
1199 条已发布资讯1199 条资讯清除筛选 ×
2026-04-30
沿着时间,追踪变化2026-04-27
沿着时间,追踪变化20:00
Workflows for work that runs the business
Workflows is now in public preview.
译文排队中,当前为原文 · en15:00
Announcing our partnership with the Republic of Korea
Google DeepMind and Korea partner to accelerate scientific breakthroughs using frontier AI models
译文排队中,当前为原文 · en2026-04-23
沿着时间,追踪变化01:00
2026-04-22
沿着时间,追踪变化18:20
Decoupled DiLoCo: A new frontier for resilient, distributed AI training
Decoupled DiLoCo: A new frontier for resilient, distributed AI training
译文排队中,当前为原文 · en00:42
2026-04-21
沿着时间,追踪变化22:54
Partnering with industry leaders to accelerate AI transformation
Google DeepMind partners with global consultancies to bring the power of frontier AI to organizations around the world.
译文排队中,当前为原文 · en2026-04-20
沿着时间,追踪变化17:00
Gradient-based Planning for World Models at Longer Horizons
GRASP is a new gradient-based planner for learned dynamics (a “world model”) that makes long-horizon planning practical by (1) lifting the trajectory into virtual states so optimization is parallel across time, (2) adding stochasticity directly to the state iterates for exploration, and (3) reshaping gradients so actions get clean signals while we avoid brittle “state-input” gradients through high-dimensional vision models. Large, learned world models are becoming increasingly capable. They can predict long sequences of future observations in high-dimensional visual spaces and generalize across tasks in ways that were difficult to imagine a few years ago. As these models scale, they start to look less like task-specific predictors and more like general-purpose simulators. But having a powe
译文排队中,当前为原文 · en2026-04-16
沿着时间,追踪变化22:41
20:18
00:03
Gemini 3.1 Flash TTS: the next generation of expressive AI speech
Our newest audio model introduces granular audio tags that give you precise control to direct AI speech for expressive audio generation.
译文排队中,当前为原文 · en2026-04-14
沿着时间,追踪变化02:15
2026-04-13
沿着时间,追踪变化23:52
Gemini Robotics-ER 1.6: Powering real-world robotics tasks through enhanced embodied reasoning
Gemini Robotics ER 1.6: Enhancing spatial reasoning and multi-view understanding for autonomous robotics.
译文排队中,当前为原文 · en2026-04-09
沿着时间,追踪变化19:22
04:01
2026-04-03
沿着时间,追踪变化16:00
00:00
Gemma 4: Byte for byte, the most capable open models
Gemma 4: Our most intelligent open models to date, purpose-built for advanced reasoning and agentic workflows.
译文排队中,当前为原文 · en2026-04-01
沿着时间,追踪变化00:16
2026-03-31
沿着时间,追踪变化20:00
Spaces: A CLI Built for Humans and Agents
Spaces: A CLI Built for Humans and Agents
译文排队中,当前为原文 · en10:03
每一次更新,都留下可追溯的来源。