3 Ways to Boost MoE Inference on NVIDIA DGX Spark
Generating tokens faster starts with identifying what limits inference performance. In the batch-size-1 evaluation of Ling-3.0-flash from Inclusion AI on NVIDIA...
Search headlines, summaries and articles to connect the dots.
Generating tokens faster starts with identifying what limits inference performance. In the batch-size-1 evaluation of Ling-3.0-flash from Inclusion AI on NVIDIA...
After the release of K3.1 Pro, due to numerous users reporting that their quotas were being depleted too quickly, Moonshot AI urgently issued an announcement stating, “The issue lies with us, and we should have fixed it sooner.” Alongside compensating affected users, Moonshot AI also indicated that it would “reduce unnecessary sub-agent calls and output lengths.” Just two days before the model went live, Anthropic published an article titled “Building agents: When to fold subagents into your main agent loop,” which addressed precisely the topic of sub-agents. Anthropic concluded that, by comparing Claude deployments across multiple companies, they found that a single agent equipped with specific skills actually outperformed “a group of...”
Author: Evin Editor: Liu Zhicheng Reviewer: Xu Xu Published by: Internet Jianghu Lately, Meta’s AI agent Muse has been all the rage. How popular is it? It has surpassed 10 million downloads in the U.S.,....
Mirendil released Fern 0.1, its first model, pretrained from scratch with a 10M-token context window. It targets agentic AI R&D work, scores 100% on RULER single needle at 10M, but trails frontier models on agentic coding. The post Mirendil Launches Fern 0.1, Its First Model, With 10M-Token Context appeared first on MarkTechPost.
1. GPT-6.1 Terra, better suited for workers, has launched, with API prices cut in half and faster computer operations On October 26, OpenAI released GPT-6.1 Terra, focusing on enhancing visual comprehension, computer operations, factual accuracy, and programming capabilities, ....
Old benchmarks approach perfect scores, yet new benchmarks consistently fall short in real-world performance. As large-model evaluation itself has become a business, companies are shifting their selection criteria from ranking-based assessments to cost‑benefit analyses.
The old “horse racing + short-cycle evaluation” approach can no longer be sustained.
Yan Deli, a senior expert at Tencent: LLMs are probabilistic models. They do not truly understand language; rather, they predict the next token (Next Token Prediction). Essentially, they are monotonous “word-chain” machines—moving forward one step at a time without retracing their path. At their core, LLMs are probabilistic models that learn, from statistical co-occurrence patterns, “what often appears alongside what,” and output “this is usually the case,” without grasping “why it is so.”...
The champion on the AI rankings may change, but the products users rely on every day don’t necessarily. The next round of competition in large models will hinge not just on whose model is stronger, but on turning a single use into a habit.
On October 19, 2026, MiniMax released its low-cost large model, M3.1Flash, which scored 42 points in comprehensive evaluations and boasts a 70% reduction in cost compared to the previous generation. However, it immediately faced accusations of “cheating on exam questions”: on AA’s publicly available past papers, it nearly achieved a perfect score, yet continued to produce the original answers even after the question stems were rewritten. Reviewers such as Cat Boss and Binkg pointed out that its performance on old and new questions is sharply divided, token consumption is abnormal, and its hallucination rate in knowledge tests reaches as high as 92.8%. On October 23, MiniMax open-sourced the model weights for independent verification, but the mechanisms behind its question-identification capabilities and the reasons for discrepancies in Chinese–English responses remain unresolved.
Why it matters:This report is based on multi‑party empirical testing (including Binkg’s re‑title experiment, the author’s replication, and a dual evaluation comparison between AA and Plotly‑Mila), verifiable data (token counts, prices, accuracy/hallucination rates), and contradictions in model behavior (English errors vs. Chinese correctness, stable performance on old tasks vs. collapse on new ones). It systematically lays out the core symptoms of the current credibility crisis in large‑model evaluations: high scores do not necessarily equate to strong generalization, and low‑price advantages create tension with the reality of model capabilities. The information source is a deep investigation authorized for publication by Titanium Media, complete with original test procedures, screenshot evidence, and timestamps, offering both timeliness and rich detail.
Author | Cynthia Editor | Zheng Xuan In 2026, the AI 3D landscape stands at a delicate crossroads. Momentum in the primary market continues to surge, with new models and startups emerging one after another, and single-image-to-3D generation now delivers photorealistic results that are almost indistinguishable from real-world objects. Yet beneath the dazzling demo façade, most generated outputs remain stuck at the “turntable showcase” stage: a meticulously crafted character or mechanical model slowly rotates under lighting, its scales, fabric folds, and metallic engravings rendered with lifelike detail. But as soon as these details enter real‑world production workflows—such as game engine rigging, industrial simulation, or 3D printing—their limitations quickly surface: structural fractures, backside collapses, fused details, and uneditable meshes begin to erupt, swallowing up the efficiency gains brought by AI through costly manual post‑processing. Fidelity in frontal views no longer equates to overall 3D quality—a consensus that’s taking hold across the industry. The race for AI‑driven 3D has shifted from the first half—“Can we generate?”—to the second half—“Can we deliver in real‑world applications?” It is precisely at this juncture that leading player Hi3D has made two strategic moves: officially open‑sourcing its production‑proven Hi3D V1.0 platform, while simultaneously launching the creator‑centric Hi3D Agent, which bridges the industry’s foundational layers and deeply embeds itself within the full creative workflow. Prior to this, the company—founded less than three years ago—had already delivered a solid track record: securing two consecutive rounds of funding within six months, totaling nearly $50 million, with top-tier investors like Sequoia China, IDG Capital, and Meituan Longzhu all participating; its Hi3D platform now serves over 120 countries and regions, supporting more than 2 million creators, and enjoys deep integrations with leading hardware manufacturers such as Tuzhu Technology and xTool. From academic breakthroughs in sparse geometry to open‑source, production‑ready models, and end‑to‑end connectivity via its Agent creation system, Hi3D has secured its ticket to the next phase of 3D generation. 01 3D Generation: Overhyped Demos, Underestimated Production Gaps The underlying logic of single‑image‑to‑3D generation inherently carries a perspective bias. As metrics like ULIP and Uni3D have repeatedly set new benchmarks, the industry’s past few years have been marked by an emphasis on front-facing views at the expense of holistic understanding, and on outward appearance rather than internal structure. However, the essence of a 3D asset lies in its ability to be rotated, edited, and manufactured as a three‑dimensional object. In a single character image, the vertical…
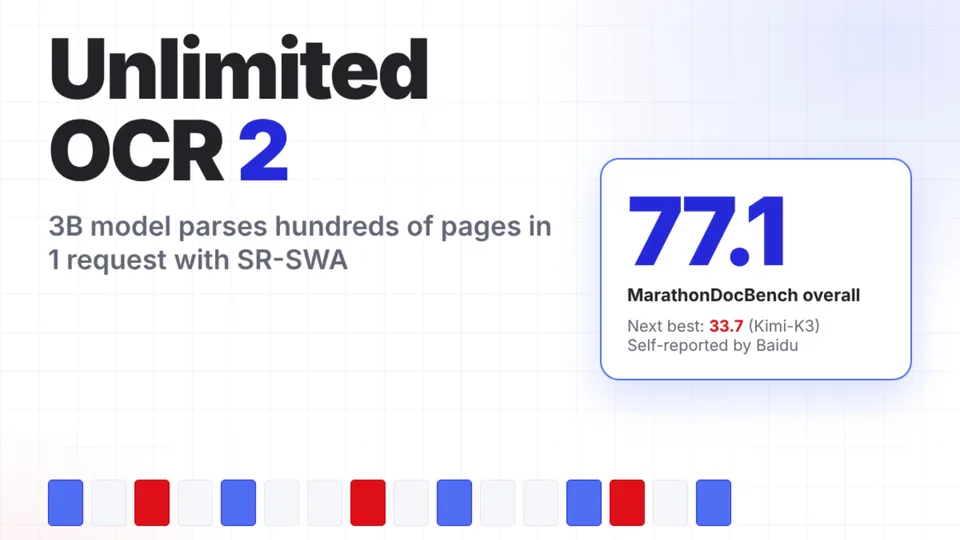
Baidu has released Unlimited OCR 2, an MIT-licensed 3B OCR model that parses hundred-page documents in one request. Its SR-SWA attention keeps per-step decoding cost nearly flat, scoring 77.1 on MarathonDocBench The post Baidu Open-Sources Unlimited OCR 2 for Hundred-Page Document Parsing appeared first on MarkTechPost.
OpenAI has once again raised the bar for the cost-effectiveness of large models. #Follow iFanr’s official WeChat account: iFanr (WeChat ID: ifanr) for more exciting content delivered to you第一时间.
OpenAI released GPT-6.1 Terra, a fast computer-use and vision model priced at $1/$5 per million tokens. It matches GPT-6 Astra’s medium-effort Agents’ Last Exam score at $0.29 per task versus $4.82. The post OpenAI Launches GPT-6.1 Terra, Halving GPT-6.1 Sol’s API Price for Agent Work appeared first on MarkTechPost.
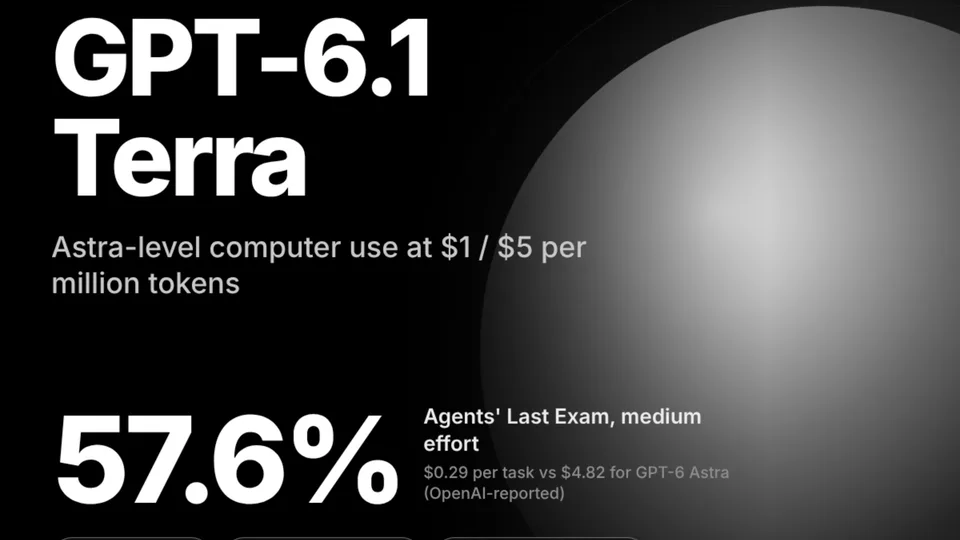
The biggest highlight is that the price has been cut in half.
An AI model said it wouldn’t use any tools, then tried to send something to a server in Beijing anyway, and while researchers say it’s probably a training quirk and not espionage, the whole thing has people asking how much to trust free Chinese AI.
OpenAI CEO Sam Altman. Image processed by AI Written by Su Yang Edited by Xu Qingyang OpenAI has once again launched a cost-effective model. On October 26, U.S. local time, Ope....
OpenAI Group PBC today released GPT-6.1 Terra, an upgrade to the middle tier model in its lineup of frontier artificial intelligence systems. The new model, the successor to GTP-5.6 Terra, costs around 50% less while handling computer use tasks faster and with greater accuracy. Terra is positioned as the everyday model in OpenAI’s lineup, designed […] The post OpenAI launches GPT-6.1 Terra for faster, better-performing AI agents at half the price appeared first on SiliconANGLE.
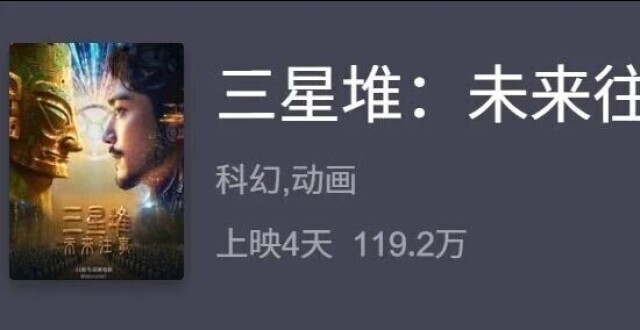
The first theatrical feature film with deep AI involvement, “Sanxingdui: Tales from the Future,” released on October 23, has seen box-office performance that starkly contrasts with the capital market’s earlier enthusiasm for the AI‑in‑film concept. According to Maoyan Professional Edition, as of noon on October 26, this 100‑minute movie had accumulated a total box office of RMB 1.192 million, with 8,469 screenings that day, an attendance rate of 0.1%, and an average of just 0.1 ticket sold per screening. On October 24 and 25, the film averaged only 2 tickets sold per screening. Data from Lighthouse Professional Edition…
Data Culture built a 3-step evaluation framework that took one AI analytics deployment from 0% accuracy to 94.7%.