
Skip to content
AI NEWS JOURNAL
AI, IN PERSPECTIVE

Search AI news

Search headlines, summaries and articles to connect the dots.

Newest first

FusionEval Released: A New Benchmark for Large Language Model Fusion

On October 24, 2026, researchers published the paper arXiv:2610.30162v1 on arXiv, introducing FusionEval—the first unified benchmark specifically designed to evaluate fusion methods for large language models. It covers vulnerable aspects such as reasoning chain length and tool invocation, and supports comparisons between fine-tuning-based and zero-shot fusion approaches.

FusionEval: Benchmarking Model Fusion for Large Language Models

Why it matters:This benchmark fills the gap left by existing evaluations, which inadequately cover long-chain reasoning and tool usage; it clearly distinguishes between average performance and worst-case capability retention, provides a reproducible expert pool (based on Qwen3/Llama), multi-dimensional metrics (including GPU memory and runtime), and open-source code, offering strong practical guidance.
Timeline and related coverage

AQL-Lite Released: An Efficient Continuous Pre-training Framework for Modern Standard Arabic

On October 24, 2026, arXiv published paper 2610.30344v1, introducing the AQL-Lite framework, which significantly enhances the adaptability of multilingual large models to Modern Standard Arabic (MSA) through quality-first data filtering and continuous pre-training of selected parameters (CPT).

AQL-Lite: Enabling Efficient Knowledge Acquisition for Arabic LLMs via Data-Centric Continual Pretraining

Why it matters:This study directly addresses key challenges in training large Arabic-language models—namely, the abundance of noisy data, dialectal diversity, and the high costs associated with continuous pre-training—by proposing a reproducible, lightweight, and cost-effective technical approach, which has been validated on multiple authoritative Arabic-language benchmarks. All conclusions are based on the experimental setup and results explicitly reported in the paper, without any external extrapolation.

Timeline and related coverage

Lighthouse: The First Trusted Digital Assistant Dedicated to the History of the U.S. Civil Rights Movement Has Been Released

The paper arXiv:2610.30158v1, published on October 24, 2026, introduces Lighthouse, the first digital assistant dedicated to exploring the history of the U.S. Civil Rights Movement, based on archival data from South Carolina. Its core innovation lies in adopting trustworthy content and user harm mitigation as design principles, employing a neuro-symbolic hybrid architecture that integrates large language models with rule-based symbolic reasoning.

Lighthouse: On Building a Trustworthy Digital Assistant for Exploring History with Civil Rights Archives

Why it matters:This study is the first to apply AI‑assisted historical exploration to the sensitive and pivotal period of the Civil Rights Movement, explicitly introducing dual constraints—“trustworthiness” and “harm modeling”—which set it apart from general‑purpose chatbots. Its methodology (neurosymbolic integration), evaluation approach (including a human‑consensus‑based gold standard for subjective questions), and data scale (over 18,000 original archival documents) all hold significant academic demonstrative value.

Timeline and related coverage

New research reveals that AI content moderation systems exhibit linguistic and cultural biases: the misclassification rate for African American English is as high as twice that of standard English.

An arXiv paper published on October 24, 2026 (ID 2610.31047v1) points out that current automated safety systems rely on lexical‑level features to assess harm, leading to systemic biases: African American English (AAE) is flagged as “offensive” up to twice as often as other English varieties; well‑known drag queen accounts are rated as more toxic than white supremacist accounts; and safety practices that work in English completely fail in low‑resource languages.

Harm Is Behavioural, Moderation Is Lexical: How Language and Culture Decide Whom Automated Safety Systems Protect and Whom They Silence

Why it matters:This study, based on an empirical evaluation protocol, covers five open-source systems and 11 languages, encompassing a total of 55 system–language combinations. It finds that 93% of these combinations fail to achieve native-speaker-level performance in hazard function recognition; moreover, improvements in model capabilities have inadvertently widened the protection gap across languages, highlighting a crisis in algorithmic fairness. The source is the arXiv preprint server, with a clearly stated publication date (2026-10-24), and the content focuses on verifiable technical flaws and cross-language empirical findings.

Timeline and related coverage

New arXiv paper compares the performance of joint scoring and item-by-item scoring for compact encoders.

On October 24, 2026, arXiv published the paper arXiv:2610.30970v1, which systematically evaluates design choices for compact encoders with model sizes ranging from 17 million to 1 billion parameters in closed-set decision-making tasks (such as tool selection): joint reading of all options versus independent scoring of each option. The study finds that, at a parameter scale of 32 million, option-by-option scoring significantly outperforms joint scoring on skill metrics; however, it incurs higher computational costs and exhibits more uneven latency. Multiple System1-Arena benchmarks show that joint encoders with 68 million and 150 million parameters surpass the 435-million-parameter DeBERTa-v3 zero-shot classifier.

Joint or Per-Option? Compact Encoders for Closed-Set Decisions from 17 Million to 1 Billion Parameters

Why it matters:This paper presents a key empirical comparison of lightweight design approaches for downstream decision-making modules in large models, covering engineering considerations such as architecture selection, initialization dependencies, the latency–accuracy trade-off, and input-order robustness. The data are based on experiments conducted with three random seeds and validated against both public and private benchmarks. The publication date (2026-10-24) matches the current UTC date (2026-10-25), making this the latest credible research advancement.

Timeline and related coverage

SIM-UT: A User Behavior Simulation and Evaluation Framework for Medical Triage Chatbots

Researchers have proposed SIM-UT (Simulation of User Behaviour for Triage), a multi-round, real-user-behavior–based evaluation method designed to identify eco‑valid failure patterns of large language model (LLM)-driven medical triage chatbots in real-world settings within low- and middle-income countries (LMICs).

SIM-UT: A User Simulation based Evaluation Framework for Medical Triage Chatbots

Why it matters:This framework breaks through the limitations of existing single-round, English‑centric evaluations by conducting over 5,000 rounds of multilingual simulated conversations, covering real‑world WhatsApp health programs in India, South Africa, and Kenya. For the first time, it systematically reveals “de‑escalation risk,” a critical failure mode, demonstrating both methodological innovation and significant clinical safety implications.

Timeline and related coverage

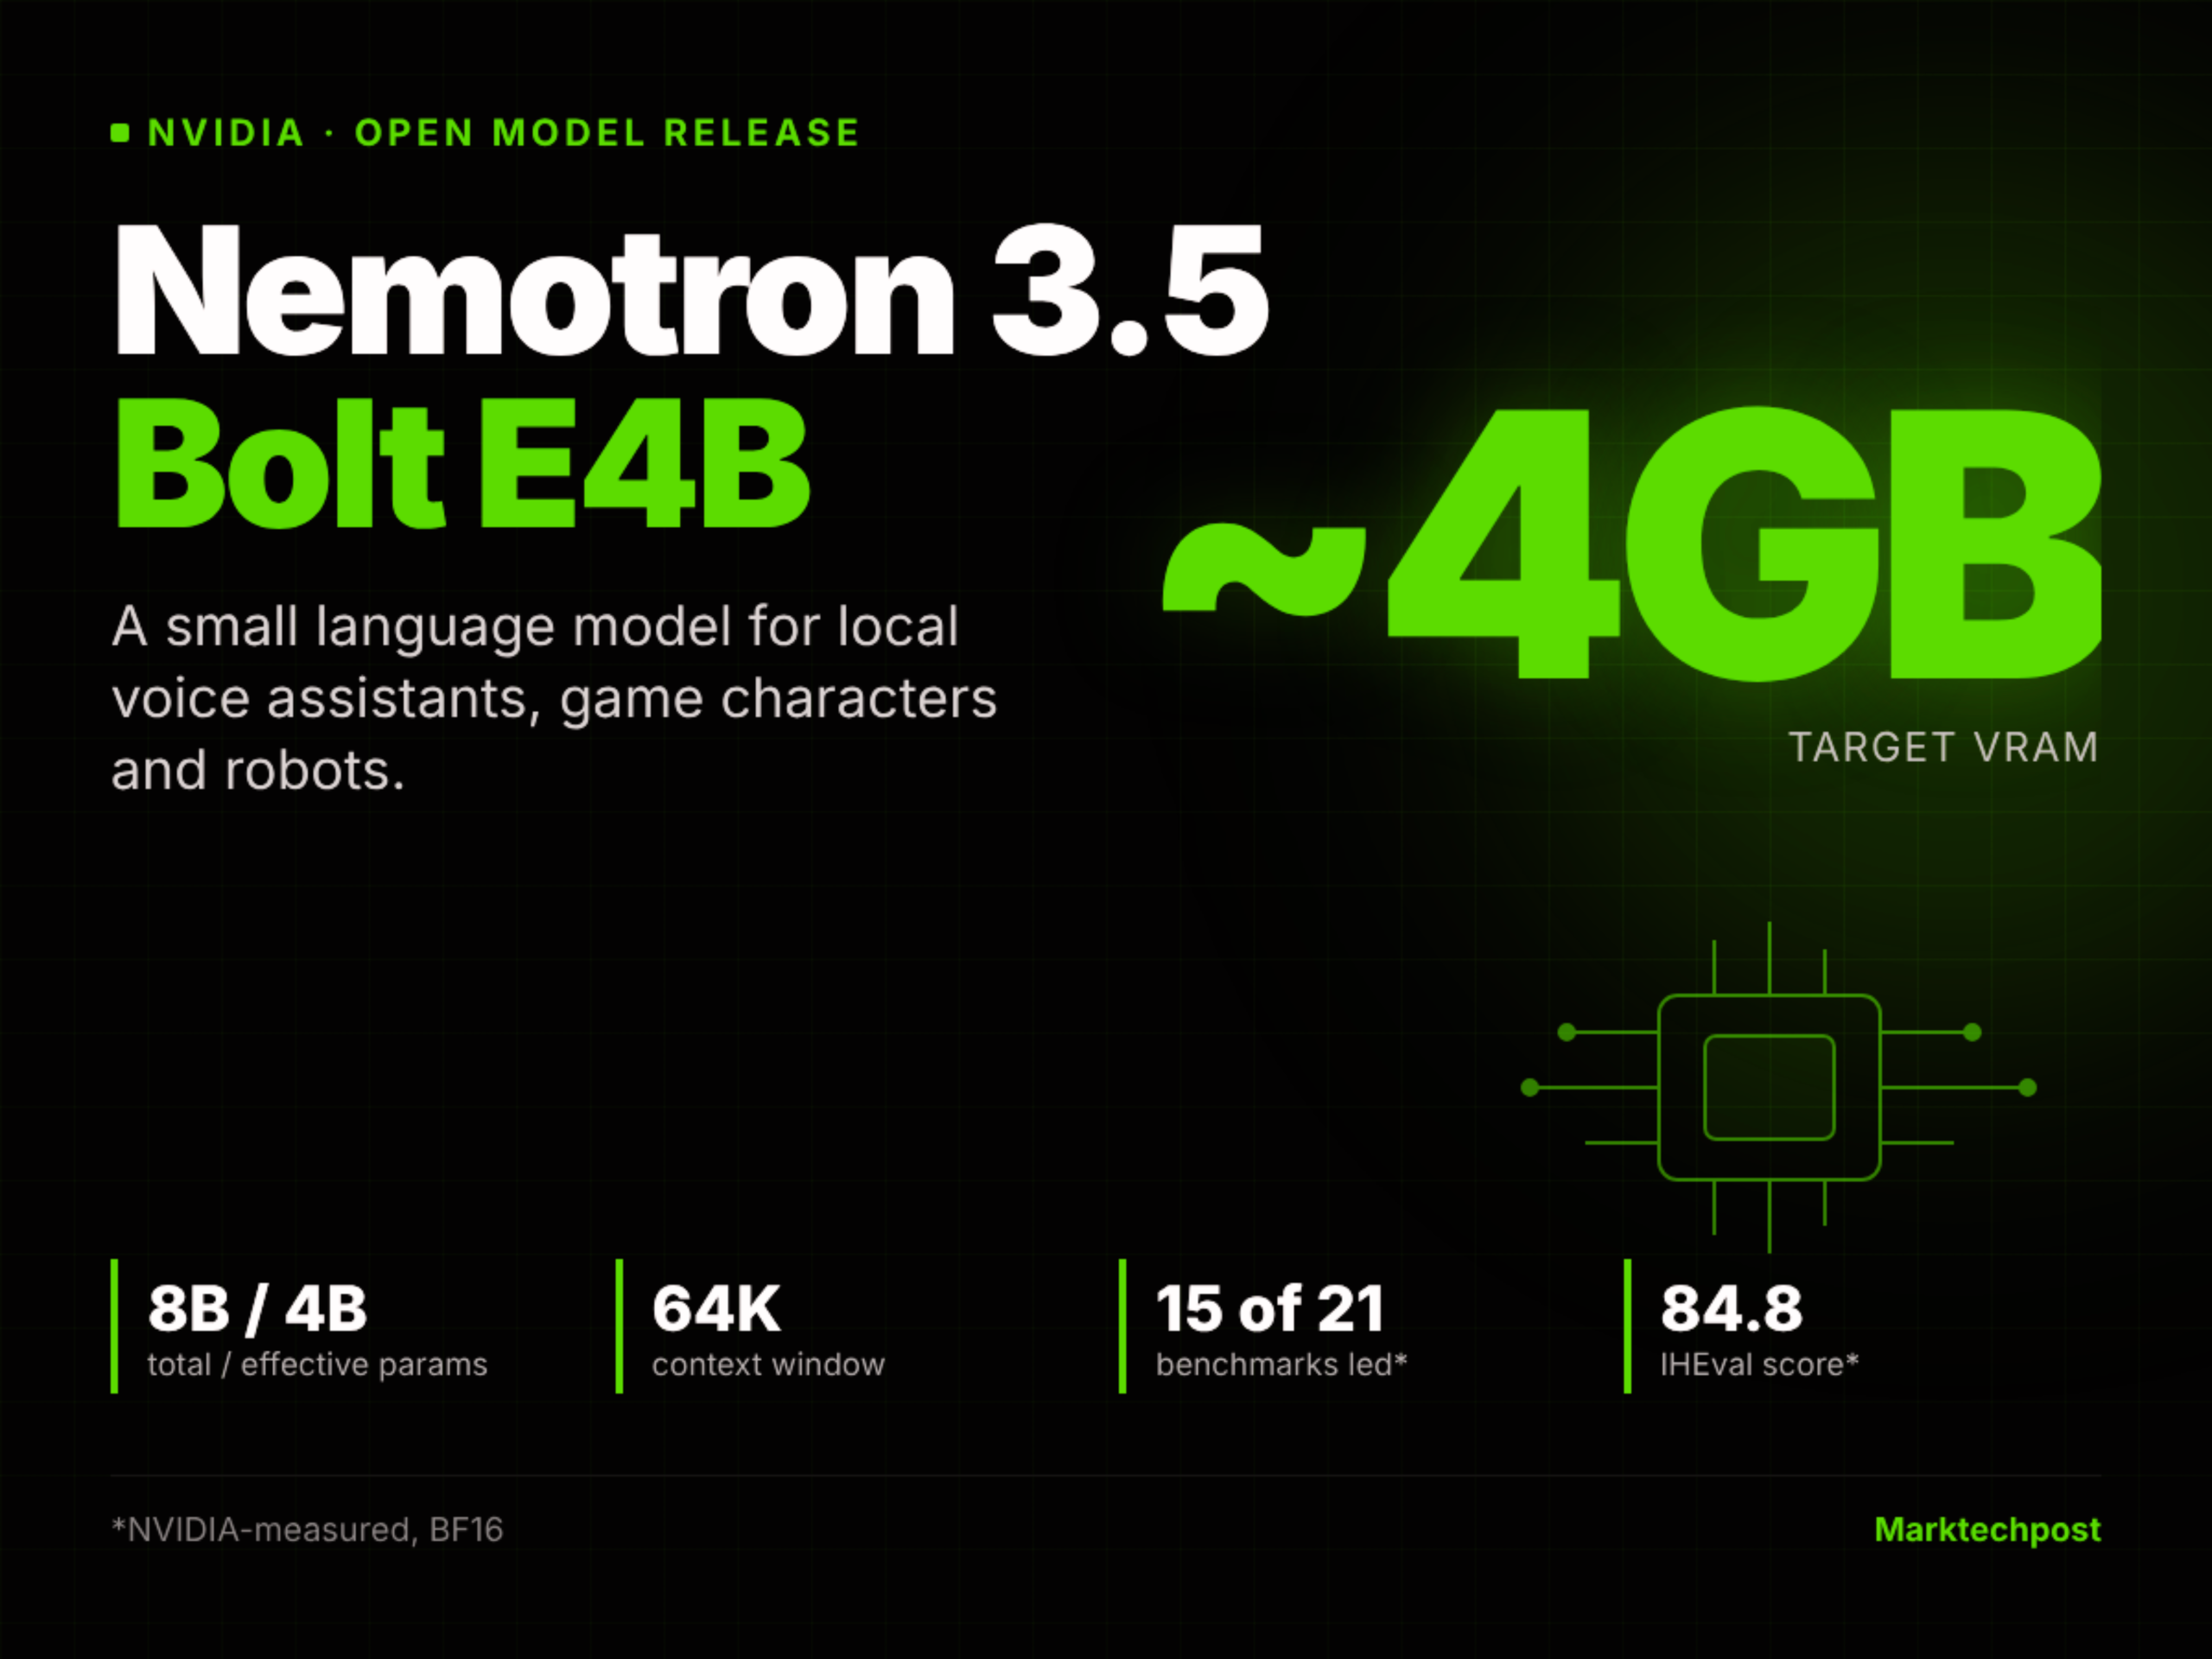
NVIDIA has released the open-source small language model Nemotron 3.5 Bolt E4B 4GB, optimized for on-device voice assistants, game NPCs, and robots.

NVIDIA, leveraging Google’s Gemma 4 E4B model and employing only reinforcement learning (RL) for post-training, has launched Nemotron 3.5 Bolt E4B 4GB—a small open-source language model with 8B total parameters, 4B effective parameters, and a 64K context window. It is designed to run on edge devices such as RTX and Jetson with approximately 4GB of VRAM, supporting multi-turn tool calls and low-latency voice interaction.

NVIDIA Releases Nemotron 3.5 Bolt E4B 4GB: An Open Small Language Model for Local Voice Agents, Game Characters and Robots
Timeline and related coverage

Block releases its new voice AI model, Dessa: trained entirely on real-world conversations, with a slightly awkward conversational style.

Jack Dorsey’s company, Block, announced the launch of an end-to-end voice AI model called Dessa, claiming it was trained entirely from scratch using only human speech dialogue data. The official demonstration samples exhibited a mix of naturalness and awkwardness—for example, mistakenly addressing a user as “Ronaldo”—highlighting its anthropomorphic yet still immature conversational capabilities.

Timeline and related coverage

Google open-sources a medical foundation model to help implement global tuberculosis screening.

Google, together with partners such as Nexus AI, has brought a chest‑X‑ray–based AI tool for tuberculosis screening from the laboratory to primary‑care settings in six countries, and has open‑sourced multimodal foundation models like MedGemma and MedSigLIP, supporting offline deployment, localized adaptation, and data sovereignty.

Timeline and related coverage

Amazon SageMaker AI has launched a Multi-Step Reinforcement Learning (MTRL) framework, supporting end-to-end training of agents to accomplish multi-step tasks.

AWS has launched the Multi-Turn Reinforcement Learning (MTRL) feature, enabling users to train large‑model agents on SageMaker AI using full task trajectories and final outcome feedback, without requiring step‑level annotations. A end-to-end demonstration is provided using Wordle as an example, covering AgentCore deployment, data preparation, GRPO training, reward design, and cost analysis.

Timeline and related coverage

Bayer Crop Science has built the multi-agent decision-making engine ADE based on Amazon Bedrock AgentCore.

Bayer Crop Science has built the Agentic Decision Engine (ADE) on Amazon Bedrock AgentCore—a natural-language multi-agent platform for breeding experts, analysts, and researchers—as an enhancement layer rather than a replacement for its existing Connected Decision Engine (CDE). The system is now live in production, serving over 100 R&D users and enabling approximately 80% of issues to be resolved independently through 22 domain-specific agents and about 20 API tools.

Timeline and related coverage