Skip to content
AI NEWS JOURNAL
AI, IN PERSPECTIVE

Search AI news

Search headlines, summaries and articles to connect the dots.

Newest first

r/opensource just banned AI, non-English speakers and more

On Saturday evening, the r/opensource moderators issued new rules prohibiting the submission of any open-source projects that are used by, generated by, or targeted at AI; they also require that projects be at least one year old, have multiple maintainers and be actively maintained. Additionally, they explicitly stated that posts from non-English-speaking users will not be accepted, citing an inability to distinguish between AI-translated and AI-generated content.

r/opensource just banned AI, non-English speakers and more
Timeline and related coverage

Researchers from Stanford and UC Berkeley Introduce TokenGate: Token-Gated Attention Makes Long-Context Prefill Up to 11.3x Faster

Researchers from Stanford University and the University of California, Berkeley have introduced TokenGate—a plug-and-play, learnable token-pruning module designed for existing large language models (LLMs). This approach accelerates the first-token generation time (TTFT) for long-context prefill by 1.4 to 11.3 times without sacrificing accuracy, while reducing peak memory usage by 1.5 to 3.4 times. The associated code and checkpoints have been made open source.

Researchers from Stanford and UC Berkeley Introduce TokenGate: Token-Gated Attention Makes Long-Context Prefill Up to 11.3x Faster
Timeline and related coverage

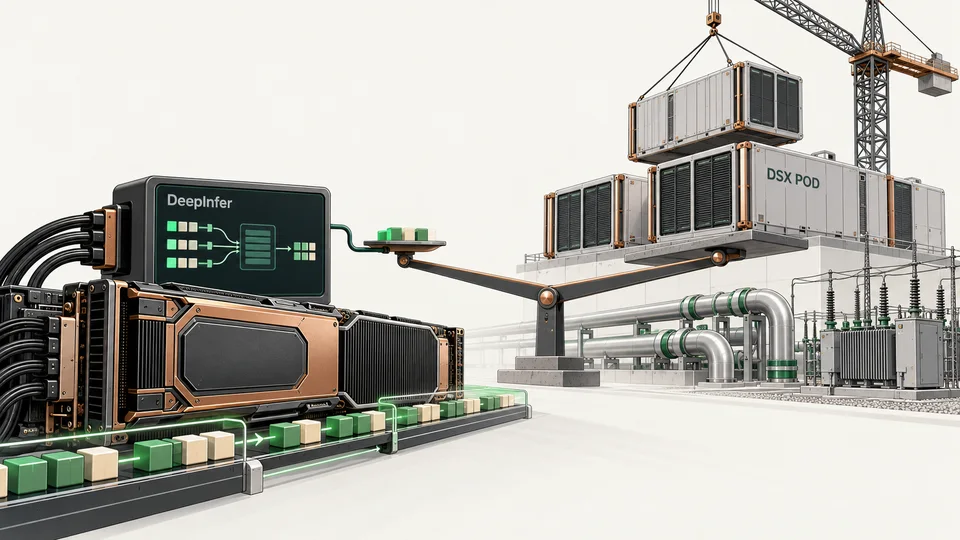
Low-Cost Intelligence vs. Expensive Ambitions: DeepInfer, DSX POD, and AI Investment Expansion

Issue 958 of “The Sequence Radar” examines inference software, modular AI factories, and enterprise AI investments side by side: cheaper per-inference does not necessarily mean lower overall industry spending. This article is compiled from the original publication and supplemented with technical scope and delivery terms based on DeepSeek and NVIDIA’s official materials.

推理软件效率与模块化AI基础设施投入的编辑示意,非实际产品照片
Timeline and related coverage

Open WebUI v0.12.4 发布:按需加载技能、上下文压缩可视化与百项无障碍及修复更新

Open WebUI v0.12.4 是一个开源大语言模型前端界面的重大维护版本,于可信元数据日期 2026-10-25 前发布。核心更新包括技能按需加载(需启用内置 Skills 工具且默认关闭)、聊天中上下文压缩过程显式标记、覆盖超百项 WCAG 合规的无障碍增强,以及 26 项经 GitHub PR/issue 验证的功能修复与行为修正,含权限控制强化、Safari/RTL/多文件夹等场景缺陷修复。未引入新模型、API 或第三方服务,无性能基准、用户数据或监管信息。

Why it matters:按信源设置仅收录,不参与自动精选

Timeline and related coverage

The PHP “Meltdown” incident reveals how AI can amplify the threat of legacy vulnerabilities.

Security researchers, using AI tools, have turned a PHP vulnerability—known collectively as PHP2Shell—that has existed for years and was once considered difficult to exploit—into a real-world exploitable attack surface. Within hours of the vulnerability being made public, it was already targeted in millions of exploitation attempts, yet no successful intrusions have been reported to date.

Why it matters:This incident clearly demonstrates for the first time that AI does not create new vulnerabilities out of thin air; rather, it significantly lowers the barrier to exploiting existing vulnerabilities, highlighting AI’s dual role in accelerating both offensive and defensive security dynamics. Moreover, all valid findings rely on human–machine collaboration.

Timeline and related coverage

Sebastian Raschka has released an eight-video course titled “Building a Reasoning Model from Scratch.”

On October 24, 2026, Sebastian Raschka published an eight-part, over-11-hour hands-on video course on Python and PyTorch in Ahead of AI magazine (magazine.sebastianraschka.com), systematically covering the evaluation of inference models, scaling during inference, reinforcement learning (RLVR), and knowledge distillation, with all methods implemented using the pre-trained Qwen3-0.6B model.

Why it matters:This course is the author’s advanced technical educational offering, following “Building Large Language Models from Scratch.” It focuses on the core evolutionary direction of today’s mainstream LLMs—enhancing inference capabilities—covering the entire technical pipeline from setting up the foundational environment to GRPO reinforcement learning and self‑distillation. The author explicitly states that all implementations are “hand‑crafted from scratch,” fully reproducible, and highly instructive with significant engineering reference value.

Timeline and related coverage

TRIAD Release: The First Multimodal Large Model Evaluation Benchmark for All-Modal Ambiguity Resolution

On October 24, 2026, researchers published the paper arXiv:2610.30841v1 on arXiv, officially introducing the TRIAD benchmark—a new evaluation framework designed to assess the ability of text–image–audio tri-modal systems to resolve cross-modal ambiguities. The benchmark comprises 327 hand-crafted tri-modal samples, spanning 86 scenario groups and 18 categories of cross-modal ambiguity types.

TRIAD: Benchmarking Omni-Modal Ambiguity in Multimodal Large Language Models

Why it matters:This achievement directly addresses a core blind spot in current multimodal large-model evaluations: existing benchmarks focus on perception or reasoning under deterministic, single-modal inputs. In contrast, TRIAD is the first to systematically target “modal-complementary disambiguation” as its evaluation objective. Through rigorously designed leave-one-modal-out counterfactual tests, it reveals critical shortcomings—particularly in audio processing—and highlights weak scene-level robustness, thereby providing a reproducible diagnostic protocol and taxonomy for assessing next-generation all‑modal models.

Timeline and related coverage

ULME Framework Achieves True Unification of Text Embedding and Language Modeling: A New Paper on arXiv Proposes a Predictive Coupling Mechanism

On October 24, 2026, arXiv published the paper arXiv:2610.30705v1, introducing ULME—a post-training framework for causal-decoder–based large language models that, through a predictive coupling mechanism, achieves, for the first time, a mutually reinforcing unification of text embedding and language-generation capabilities. This approach was validated on the Qwen2.5/Qwen3 series (with 0.5B–8B parameters), yielding MTEB improvements of 3.3–4.1 points while maintaining performance on generation tasks such as MMLU.

ULME: Predictive Coupling for Mutually Reinforcing Embedding and Language Modeling

Why it matters:This paper directly addresses the core issue of fragmented multimodal LLM capabilities: embeddings and generation have long been handled either by separate models or by “pseudo-unified” models that rely solely on parameter sharing. ULME achieves a substantial architectural breakthrough by employing learnable slots and joint training with three objectives—including a stop-gradient prediction loss—enabling the generation process to actively shape the embedding representations. The study features broad experimental coverage, strong baselines, comprehensive metrics, and was published on a reputable preprint platform, balancing timeliness with technical rigor.

Timeline and related coverage

TutorCaseBench Released: The First LLM Tutoring Evaluation Benchmark for Special Education Scenarios

On October 24, 2026, researchers published TutorCaseBench on arXiv (ID 2610.30828v1)—an LLM tutoring evaluation benchmark built on real-world cases from pedagogy, educational psychology, and special education, focusing on the ability to support students with learning and behavioral challenges. The benchmark comprises 923 dialogue segments, covering five categories of challenging behaviors, and employs a dual-track assessment approach: open-ended generation (1,560 questions) and multiple-choice questions (2,537 questions). Among 11 state-of-the-art large models, the top performer met the evaluation criteria in only 55.8% of the open-ended items.

TutorCaseBench: A Case-Grounded Benchmark for Evaluating LLM Tutors in Supporting Students with Challenging Behaviors

Why it matters:This study fills a critical gap in existing AI‑based educational assessment, which has overlooked the complexity of students with special needs. Its methodology emphasizes evidence‑based tracing—combining qualitative case studies with source‑grounded rubrics—and all data are openly available, ensuring reproducibility and relevance to educational practice. The findings clearly reveal significant shortcomings of current LLMs in generating contextually appropriate responses, offering important warnings and guidance for the practical implementation of educational AI.

Timeline and related coverage

Clinicians Lead the Development of Verifiable Safety Guidelines: Establishing a Traceable Layer of Safeguards for Mental Health Chatbots

On October 24, 2026, arXiv published the paper arXiv:2610.30690v1, which proposes a four‑rule safety‑check rulebook defined, finalized, and adjudicated under the guidance of two clinical physicians. After formal verification, this rulebook is deployed as a guardrail layer to govern the outputs of large language models (LLMs) in mental health contexts. All judgments within this guardrail can be traced back to a single naming rule and sixteen factual verifications, aiming to enhance the interpretability and testability of safety assessments.

From Clinical Judgment to Checkable Rules: Clinician-Led Guardrails for Mental-Health Chatbots

Why it matters:This study offers a safety‑enhancing approach distinct from mainstream prompt engineering, LLM‑as‑a‑Judge, or Constitutional AI. Its core innovation lies in structuring and formalizing clinical decision‑making while maintaining a complete audit trail throughout the process. All key claims—such as the number of rules, validation methods, factual base, comparative experimental data, and cost metrics—are explicitly stated in the original text, and the publication date (2026‑10‑24) aligns with the current UTC date (2026‑10‑25), ensuring timeliness and a solid foundation of credibility.

Timeline and related coverage

Aggregated scores in LLM evaluations mask the instability of individual judgments: New research from Arena-Hard reveals instruction sensitivity.

The study employed 500 Arena-Hard v2.0 prompts, with responses from two models held constant, and used GPT‑4.1 as the judge. Under eight instruction combinations, repeated evaluations revealed that even when aggregate scores varied only slightly (e.g., by ±1 point), up to 21.2% of individual prompt outcomes (win/draw/loss) changed; further adjustments to the instructions amplified this instability, leading to an additional 28.2 percentage points in outcome shifts, while the aggregate scores themselves remained virtually unchanged.

Behind Aggregate Scores: What Systematically Varying Arena-Hard's LLM Judge Reveals

Why it matters:The study directly addresses a core blind spot in current LLM evaluation practices—overreliance on aggregate scores while neglecting the reproducibility of individual judgments and instruction dependency—providing critical methodological warnings for tasks that rely on fine-grained assessments, such as preference modeling and reinforcement learning from human feedback (RLHF).

Timeline and related coverage

The study proposes a self-assessment reinforcement learning framework, SARL, which enhances the search state-awareness capability of retrieval-augmented large models.

On October 24, 2026, arXiv published the paper arXiv:2610.30435v1, introducing the Self-Assessment Reinforcement Learning (SARL) framework, which aims to address the issue in existing retrieval-augmented large language models where search agents lack the ability to perceive search states.

Self-Assessment Reinforcement Learning for Search-State Awareness in Retrieval-Augmented Large Language Models

Why it matters:This study addresses a critical limitation of retrieval-augmented large language models—namely, their tendency to generate hallucinatory reasoning and prematurely terminate searches when they fail to recognize previously acquired or missing information in complex tasks. It proposes an end-to-end reinforcement learning approach that requires no additional evaluation during testing, achieving significant performance improvements on multi-hop reasoning and deep-research benchmarks.

Timeline and related coverage

TauIndianBankBench Released: A Program-Aware Dialogue Agent Evaluation Benchmark for the Indian Retail Banking Sector

On October 24, 2026, researchers published TauIndianBankBench on arXiv (ID 2610.30161v1)—a task-oriented benchmark comprising 1,000 tasks, specifically designed to evaluate whether language-model–driven banking dialogue agents strictly adhere to operational procedures (such as obtaining a final settlement quote before closing an account), rather than relying solely on the final record to determine success or failure.

TauIndianBankBench: Procedure-Aware, Action-Oriented Evaluation of Tool-Using Conversational Agents

Why it matters:This benchmark directly addresses current blind spots in LLM evaluation: traditional methods only verify the final state of a dialogue, leading to 6.5–12.0% of sessions involving procedural jumps or unauthorized actions being mistakenly classified as successful; its program-aware design fills a critical gap in compliance assessment for business automation in the Indian banking sector.

Timeline and related coverage

IndoNutriQA, the Indonesian clinical nutrition Q&A benchmark, has been officially released.

On October 24, 2026, the research team published a paper on arXiv (ID 2610.31256v1), introducing IndoNutriQA, the first expert-annotated question-answering benchmark for the Indonesian-language clinical nutrition domain. It comprises 911 question–answer pairs derived from real clinical reports, focusing on evaluation rather than training, and supports generative, extractive, and retrieval-augmented question-answering tasks.

IndoNutriQA: An Indonesian Clinical Nutrition Question Answering Benchmark

Why it matters:This benchmark fills the gap in high-quality publicly available evaluation data for low-resource languages—particularly Indonesian—in the clinical nutrition NLP domain. It features comprehensive structured metadata, question types that strictly adhere to the Nutrition Care Process (NCP), and has undergone expert validation and multi‑model benchmarking, ensuring a clear research focus and rigorous methodology.

Timeline and related coverage

New research casts doubt on the effectiveness of context-enhanced methods in reasoning: any gains in accuracy may be due to random fluctuations.

An AI research paper published on October 24, 2026, on arXiv (ID 2610.30983v1) systematically evaluated five context‑enhanced reasoning methods and found that the reported accuracy improvements may not reflect genuine gains in capability but could instead stem from undirected perturbations—correcting some predictions while simultaneously undermining others.

A Reality Check of Inference-Time Context Augmentation Methods

Why it matters:This paper for the first time establishes a unified evaluation framework that spans methods, models, and datasets, pointing out that relying solely on performance gains can easily obscure reliability shortcomings. In particular, it warns that filler-token–based approaches (which do not introduce new information) primarily perturb predictions near the decision boundary and should therefore not be deployed directly in real-world applications.

Timeline and related coverage

New research introduces the Cross-Language Poor-Condition Stimuli (CPOS) experimental paradigm, revealing the conditional transfer of hierarchical generalization capabilities in language models.

On October 24, 2026, arXiv published paper 2610.30960v1, introducing the Cross-Language Poor-Condition Stimulus (CPOS) experimental design to quantify language models’ ability to transfer hierarchical structural knowledge from a source language (L1) to a target language (L2) during cross-language continual training. The experiments show that this transfer partially holds but is imperfect, and it heavily depends on the specific language pair and the degree of lexical overlap.

Once a Tree, Always a Tree? Cross-lingual Transfer of Hierarchical Generalization in Language Models

Why it matters:This study is the first to construct a controllable cross-linguistic minimal-stimulus framework, directly testing whether “universal linguistic structures” constitute the cognitive basis for cross-linguistic transfer, rather than being driven solely by non-linguistic factors (such as positional encoding initialization). Its findings hold both methodological and theoretical value for understanding the mechanisms of grammar acquisition in large language models and multi-language alignment strategies.

Timeline and related coverage

MemPlan: A Memory-Augmented PDDL Planning Framework for Partially Observable Textual Environments

The paper was published on arXiv on October 24, 2026 (ID 2610.30379v1), introducing MemPlan—a memory-conditioned PDDL planning framework that uses large language models (LLMs) as a constrained bridge between linguistic and symbolic planning, suitable for partially observable interactive text-based environments.

MemPlan: Memory-Conditioned PDDL Planning for Partially Observable Text Environments

Why it matters:MemPlan dynamically reformulates PDDL problems using forward-graph memory and backward-memory mechanisms, significantly improving task success rates and step efficiency while substantially reducing online token consumption. Its offline fine-tuned language–symbol interface can be reused across TextWorld task types without requiring task-specific fine-tuning, demonstrating the method’s generalizability and practicality.

Timeline and related coverage

Consistency Does Not Equal Effectiveness: Self-Rewarding Moral Reasoning Makes Large Language Models More Decisive but More Susceptible to Manipulation

The study, posted on arXiv on October 24, 2026 (ID 2610.30349v1), proposes a method for training large language models to make ethical judgments by self-assessing the quality of their own reasoning. It finds that the model exhibits more consistent behavior—i.e., becomes more “decisive”—when the order of options is varied, but this does not improve the effectiveness of its ethical judgments and it still suffers from sycophancy and reframing issues.

Consistency Is Not Validity: Self-Rewarded Moral Argumentation Makes Language Models Decisive but Pliable

Why it matters:The paper challenges the prevailing assumption that behavioral consistency—such as sequence invariance—serves as a proxy for moral reasoning capability, empirically demonstrating that consistency can be optimized without improving the quality of substantive judgments, thereby offering important cautionary insights for methodologies used in AI ethics assessment.

Timeline and related coverage

New research introduces the ReflectPO framework, enhancing the autonomous error-correction capabilities of large language model agents in long-term tasks.

On October 24, 2026, arXiv published a research paper titled “ReflectPO: Reflection-Guided Policy Optimization for Long-Horizon LLM Agents” (ID 2610.30933v1), introducing a reinforcement learning framework called ReflectPO, designed to enhance the autonomous error-recovery capabilities of tool-augmented large language model agents in complex, multi-step, state-dependent tasks.

ReflectPO: Reflection-Guided Policy Optimization for Long-Horizon LLM Agents

Why it matters:This paper is a cutting-edge AI study recently published, focusing on a key bottleneck in the real-world deployment of LLM-based agents: the cumulative effect of early errors in long‑term tasks. Its proposed dual-component design—Reflection‑Guided Sampling and Tree‑Structured Credit Assignment—features methodological innovation and empirically outperforms multiple baselines across two benchmarking scenarios, making it a valuable technical reference.

Timeline and related coverage

Research finds that word length can directly indicate the identity of Mandarin homophones: a new arXiv paper reveals the cognitive link between word frequency and pronunciation duration.

On October 24, 2026, arXiv published a new paper titled “Direct Prompting of Word Length for Lexical Identity: Evidence from Mandarin Chinese Homophones” (arXiv:2610.30682v1), reporting experiments that show that, in the absence of other phonetic cues or under high-noise conditions, native Mandarin speakers can infer word frequency based on differences in the pronunciation duration of disyllabic homophones—shorter pronunciations tend to be identified as high-frequency words. This suggests that word length may be encoded as a phonetic detail in the mental lexicon and contribute to spoken-word recognition.

Direct cueing of word identity through word duration: evidence from Mandarin homophones

Why it matters:This study takes the rich inventory of disyllabic homophones in Chinese as its starting point, employs a homophone ranking task while controlling for word frequency, and tests the functional role of word length under stringent auditory conditions. The findings provide new evidence for a cross-linguistic phonological implementation mechanism underlying the “word-frequency effect” and challenge the traditional view that word length is merely a paralinguistic phenomenon, bearing dual implications for psycholinguistics and speech-perception theory.

Timeline and related coverage