Skip to content
AI NEWS JOURNAL
AI, IN PERSPECTIVE

Search AI news

Search headlines, summaries and articles to connect the dots.

Newest first

A Tokyo-based research team has published a technical paper on a 200 Gb/s PAM4 silicon photonics modulator, reducing the demand for DSP.

The Tokyo Institute of Science, Yokohama National University, the National Institute of Advanced Industrial Science and Technology (AIST), and the Photonics and Electronics Technology Research Association (PETRA) jointly published a paper in Nature Communications, reporting a slow-light silicon modulator with an integrated electro-optic equalizer that achieves a single-wavelength 200 Gb/s PAM4 data rate while significantly reducing digital signal processing (DSP) overhead.

Silicon Photonic Modulator Reaches 200 Gb/s PAM4 With Reduced DSP (Science Tokyo, Yokohama, AIST, PETRA)

Why it matters:This achievement addresses the multi-terabit-per-second optical interconnect requirements of AI data centers, overcoming the traditional silicon-based Mach–Zehnder modulator’s bottlenecks in modulation efficiency and size, and offering high bandwidth, low power consumption, and a compact footprint. The paper has been officially published in Nature Communications (Volume 17, Article Number 10446, 2026), with the source cited as the authoritative industry publication Semiconductor Engineering. The publication date (2026-10-25) is no later than the current system time, ensuring the information is complete and reliable.

Timeline and related coverage

LangChain releases the five core components of its “Enterprise-Level Agent Framework”

On October 25, 2026, LangChain published a blog post systematically outlining the five universal architectural principles it has distilled from deploying AI agents (GTM Agent, OpenSWE, Content Studio) within its marketing, sales, and engineering teams: native integration with the work environment (Slack), a dynamic identity model (OBO + fixed credentials), a two-tiered memory mechanism (global/user-level), sandboxed code execution, and a high proportion of scheduled operations (not manually triggered). All agents are built on the Managed Deep Agents platform.

Why it matters:This information originates from the official LangChain blog, published on 2026-10-25T18:06:32.000Z—earlier than the current system time of 2026-10-25T23:01:18.857Z. The content focuses on implemented internal agent practices, with specific details such as Slack thread isolation, GitHub account attribution logic, and tiered permissions for Notion/Twitter, without including unverified predictions or external claims, thus meeting requirements for timeliness and factual accuracy.

Timeline and related coverage

Researchers from Stanford and UC Berkeley Introduce TokenGate: Token-Gated Attention Makes Long-Context Prefill Up to 11.3x Faster

Researchers from Stanford University and the University of California, Berkeley have introduced TokenGate—a plug-and-play, learnable token-pruning module designed for existing large language models (LLMs). This approach accelerates the first-token generation time (TTFT) for long-context prefill by 1.4 to 11.3 times without sacrificing accuracy, while reducing peak memory usage by 1.5 to 3.4 times. The associated code and checkpoints have been made open source.

Researchers from Stanford and UC Berkeley Introduce TokenGate: Token-Gated Attention Makes Long-Context Prefill Up to 11.3x Faster
Timeline and related coverage

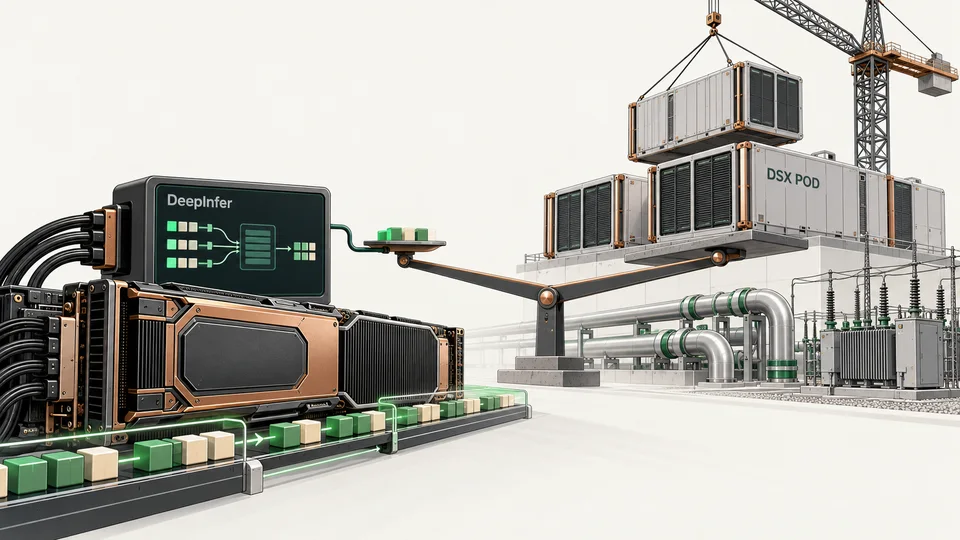
Low-Cost Intelligence vs. Expensive Ambitions: DeepInfer, DSX POD, and AI Investment Expansion

Issue 958 of “The Sequence Radar” examines inference software, modular AI factories, and enterprise AI investments side by side: cheaper per-inference does not necessarily mean lower overall industry spending. This article is compiled from the original publication and supplemented with technical scope and delivery terms based on DeepSeek and NVIDIA’s official materials.

推理软件效率与模块化AI基础设施投入的编辑示意,非实际产品照片
Timeline and related coverage

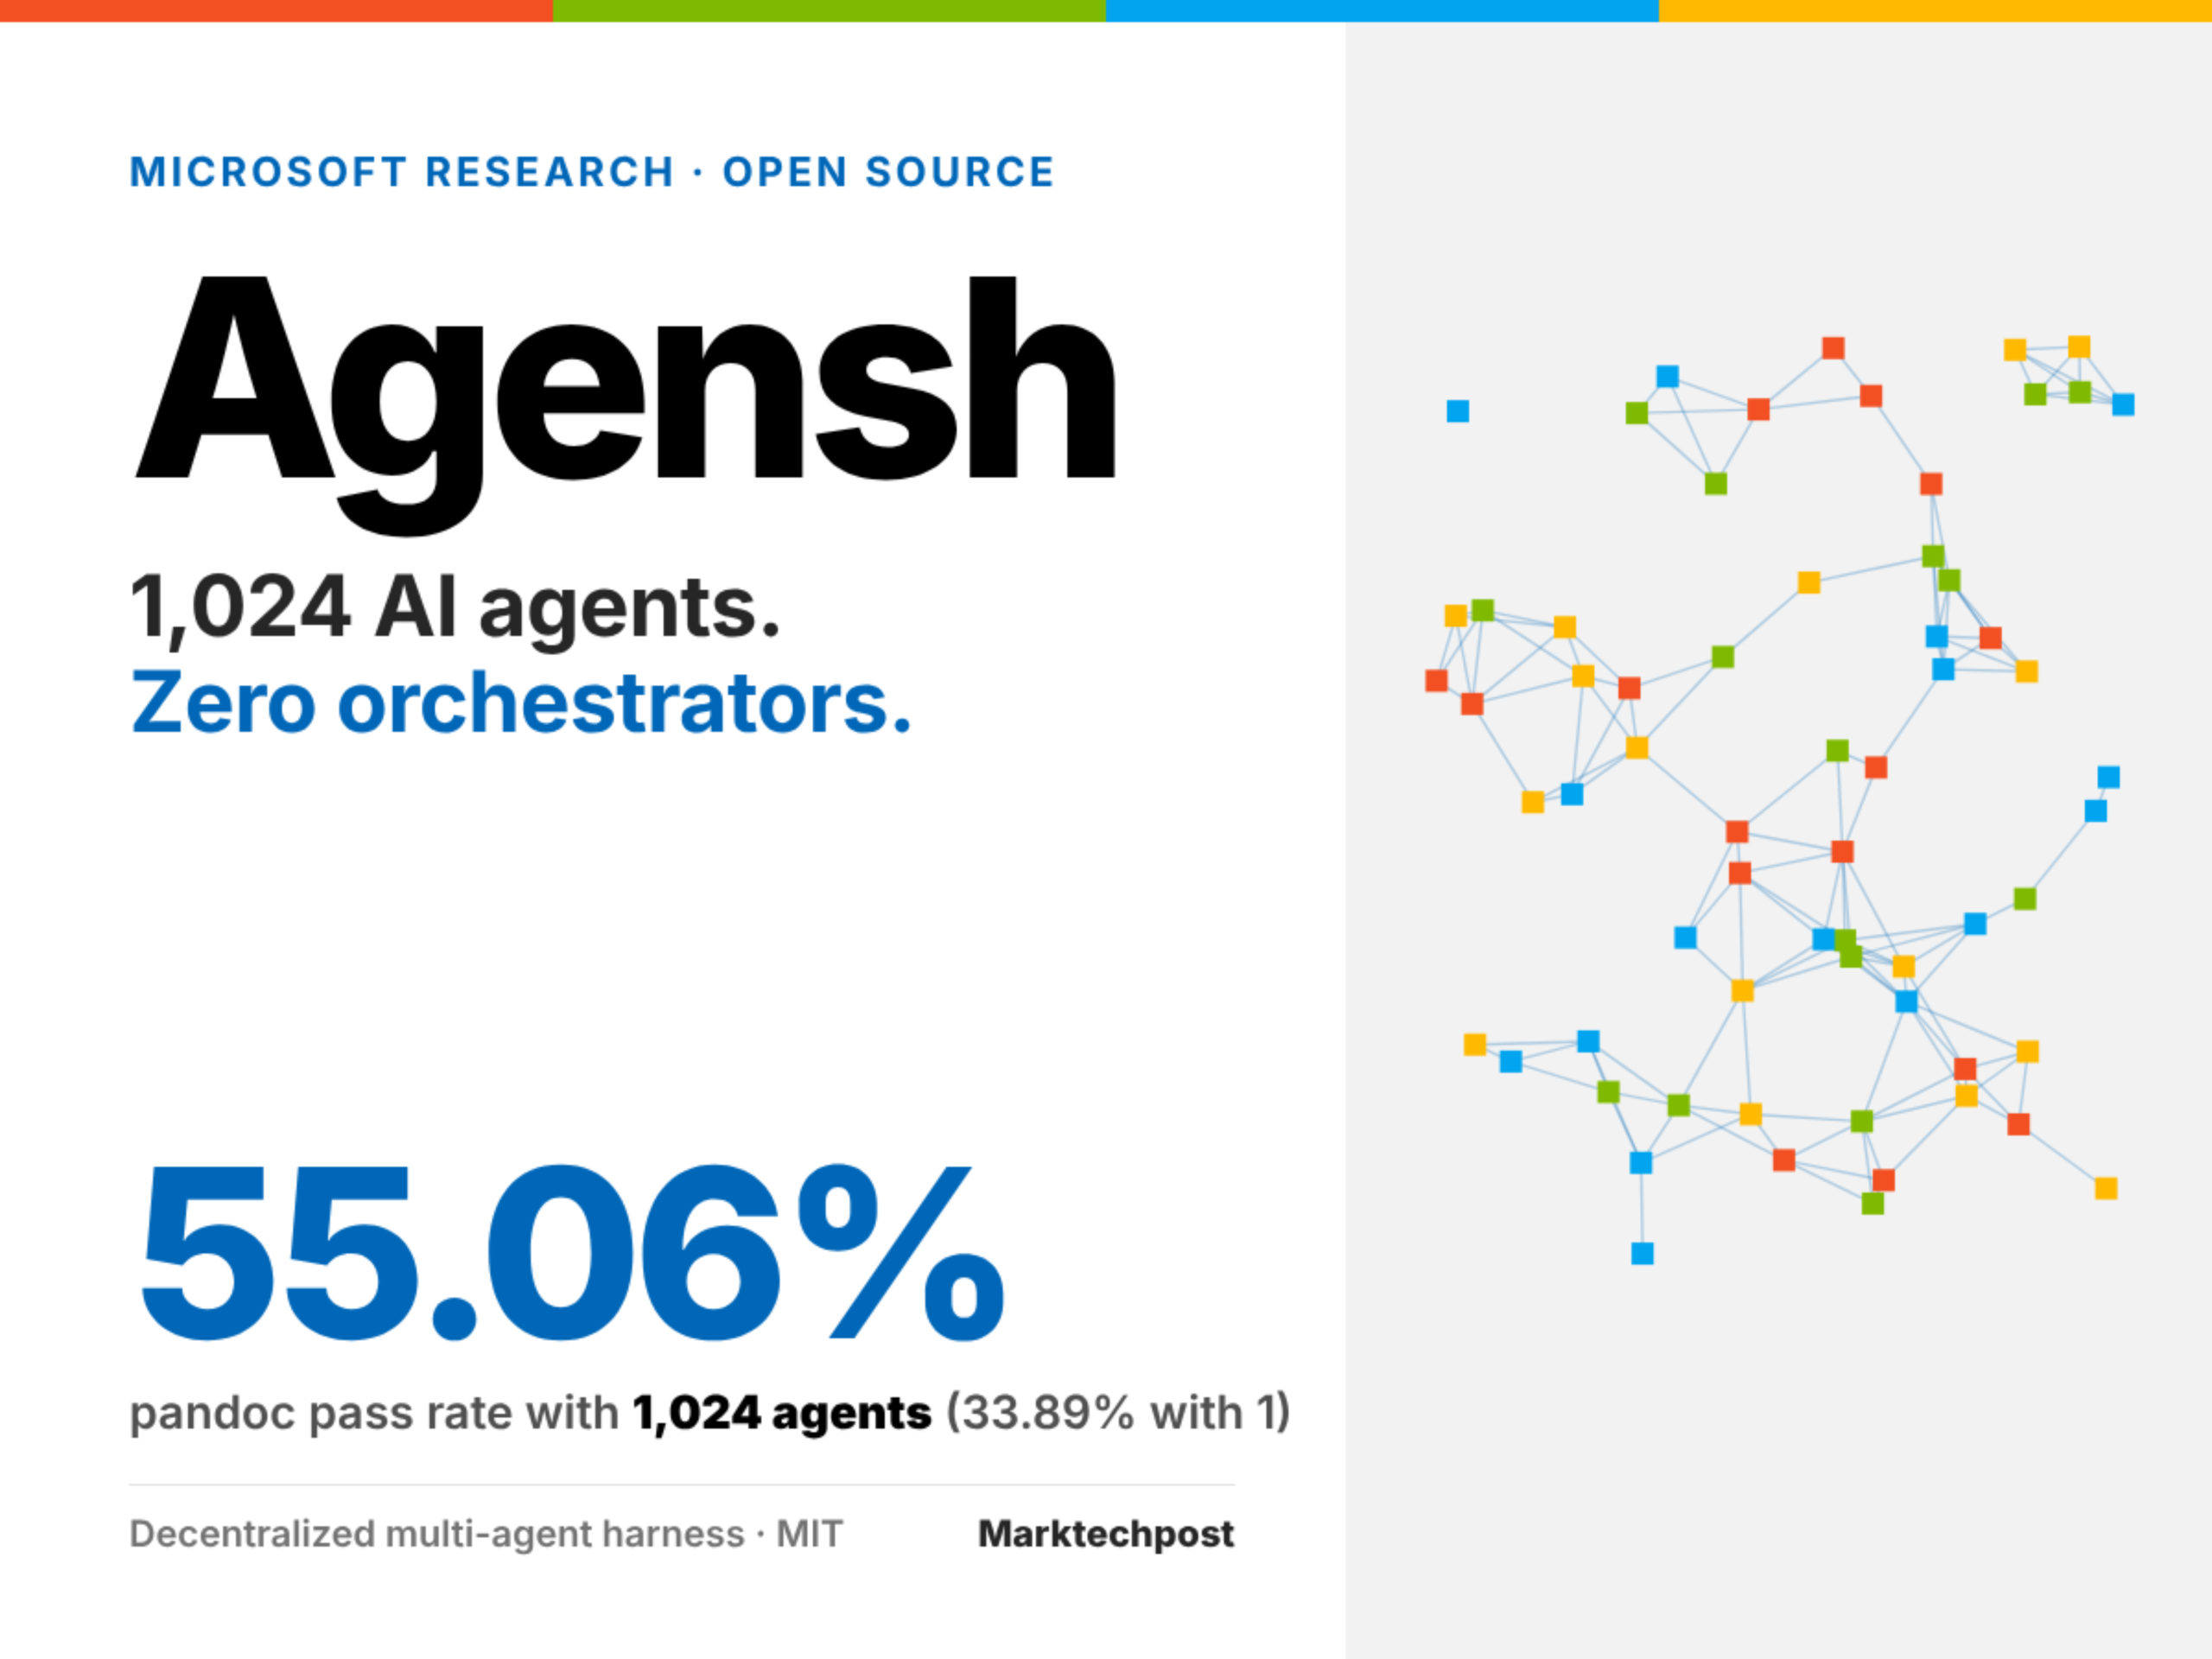
Microsoft open-sources Agensh: a decentralized framework that supports 1024 autonomous, collaboratively operating AI coding agents.

On October 25, 2026, Microsoft Research open-sourced Agensh, a multi-agent runtime framework that operates without a central coordinator, enabling 1 to 1,024 LLM-powered coding agents to self-organize and collaborate on ProgramBench. The system achieves decentralized coordination through shared dashboards inspired by Gitea, Mattermost, and DeLM, with all agents following the same prompt-driven five-step loop; its scalability has been validated in a Linux + Docker environment.

Microsoft Open-Sources Agensh: A Multi-Agent Harness for 1,024 Agents

Why it matters:This achievement represents a significant evolution in multi-agent system architectures—abandoning the traditional “master‑agent” paradigm and enabling large‑scale self‑organization through prompt engineering and lightweight service composition. Empirical results on ProgramBench (e.g., 128 agents achieving a 49% improvement in task load balancing across five tasks) establish a new benchmark for distributed AI engineering. Released under the MIT License and compatible with mainstream single‑agent tools such as Copilot CLI, it offers valuable guidance for practical development.

Timeline and related coverage

AI-driven market trends don’t undermine earnings—only valuations: Q3 reports confirm order visibility, and investors are bucking the trend by increasing positions.

From September 22 to October 22, 2026, the A-share AI sector continued to adjust, with the ChiNext Index falling 24.20% and the STAR 50 PE-TTM dropping nearly 60%, from 264 times to above 110 times. Meanwhile, corporate earnings collectively exceeded expectations during the same period—CATL reported a quarterly net profit of RMB 21.2 billion, Yuanjie Technology forecast a nearly sixfold increase, and Lianxun Instruments posted a net profit surge of over 18 times—while equity ETFs saw net inflows of nearly RMB 70 billion. The core driver of this correction was valuation compression, rather than deteriorating fundamentals.

Why it matters:The material explicitly states that the primary drivers of this round of decline are the rising discount rate (affecting the denominator) and weakening overseas regulatory expectations (eroding confidence on the numerator), which together have weighed on valuations—while industry conditions, order visibility, primary-market pricing, and policy‑exemption arrangements have all remained stable. Meanwhile, continued net ETF subscriptions and a spate of announcements from optical‑module companies indicating order backlogs extending through 2027 further confirm that the market is actively stepping in at low valuation levels, with a clear rationale and a fully substantiated chain of evidence.

Timeline and related coverage

AI Graveyard: A Continuously Updated List of Failed AI Projects and Startups

TechCrunch reported on October 25, 2026, reviewing several AI projects from 2023 to 2026 that failed to meet expectations, including startups and products such as Relay, Character.ai, Sora, and Humane AI Pin, as well as failed attempts or major adjustments by major companies like OpenAI, Apple, and Microsoft.

The AI graveyard: a running list of projects and startups that didn’t make it

Why it matters:This report provides an industry‑wide, phenomenon‑driven overview, with broad coverage and a clear timeline (including specific shutdown or delay dates), and cites S&P Global Market Intelligence data to substantiate the high attrition rate—42%—of enterprise‑level AI projects. It combines detailed case studies with structural analysis, making it a highly valuable reference.

Timeline and related coverage

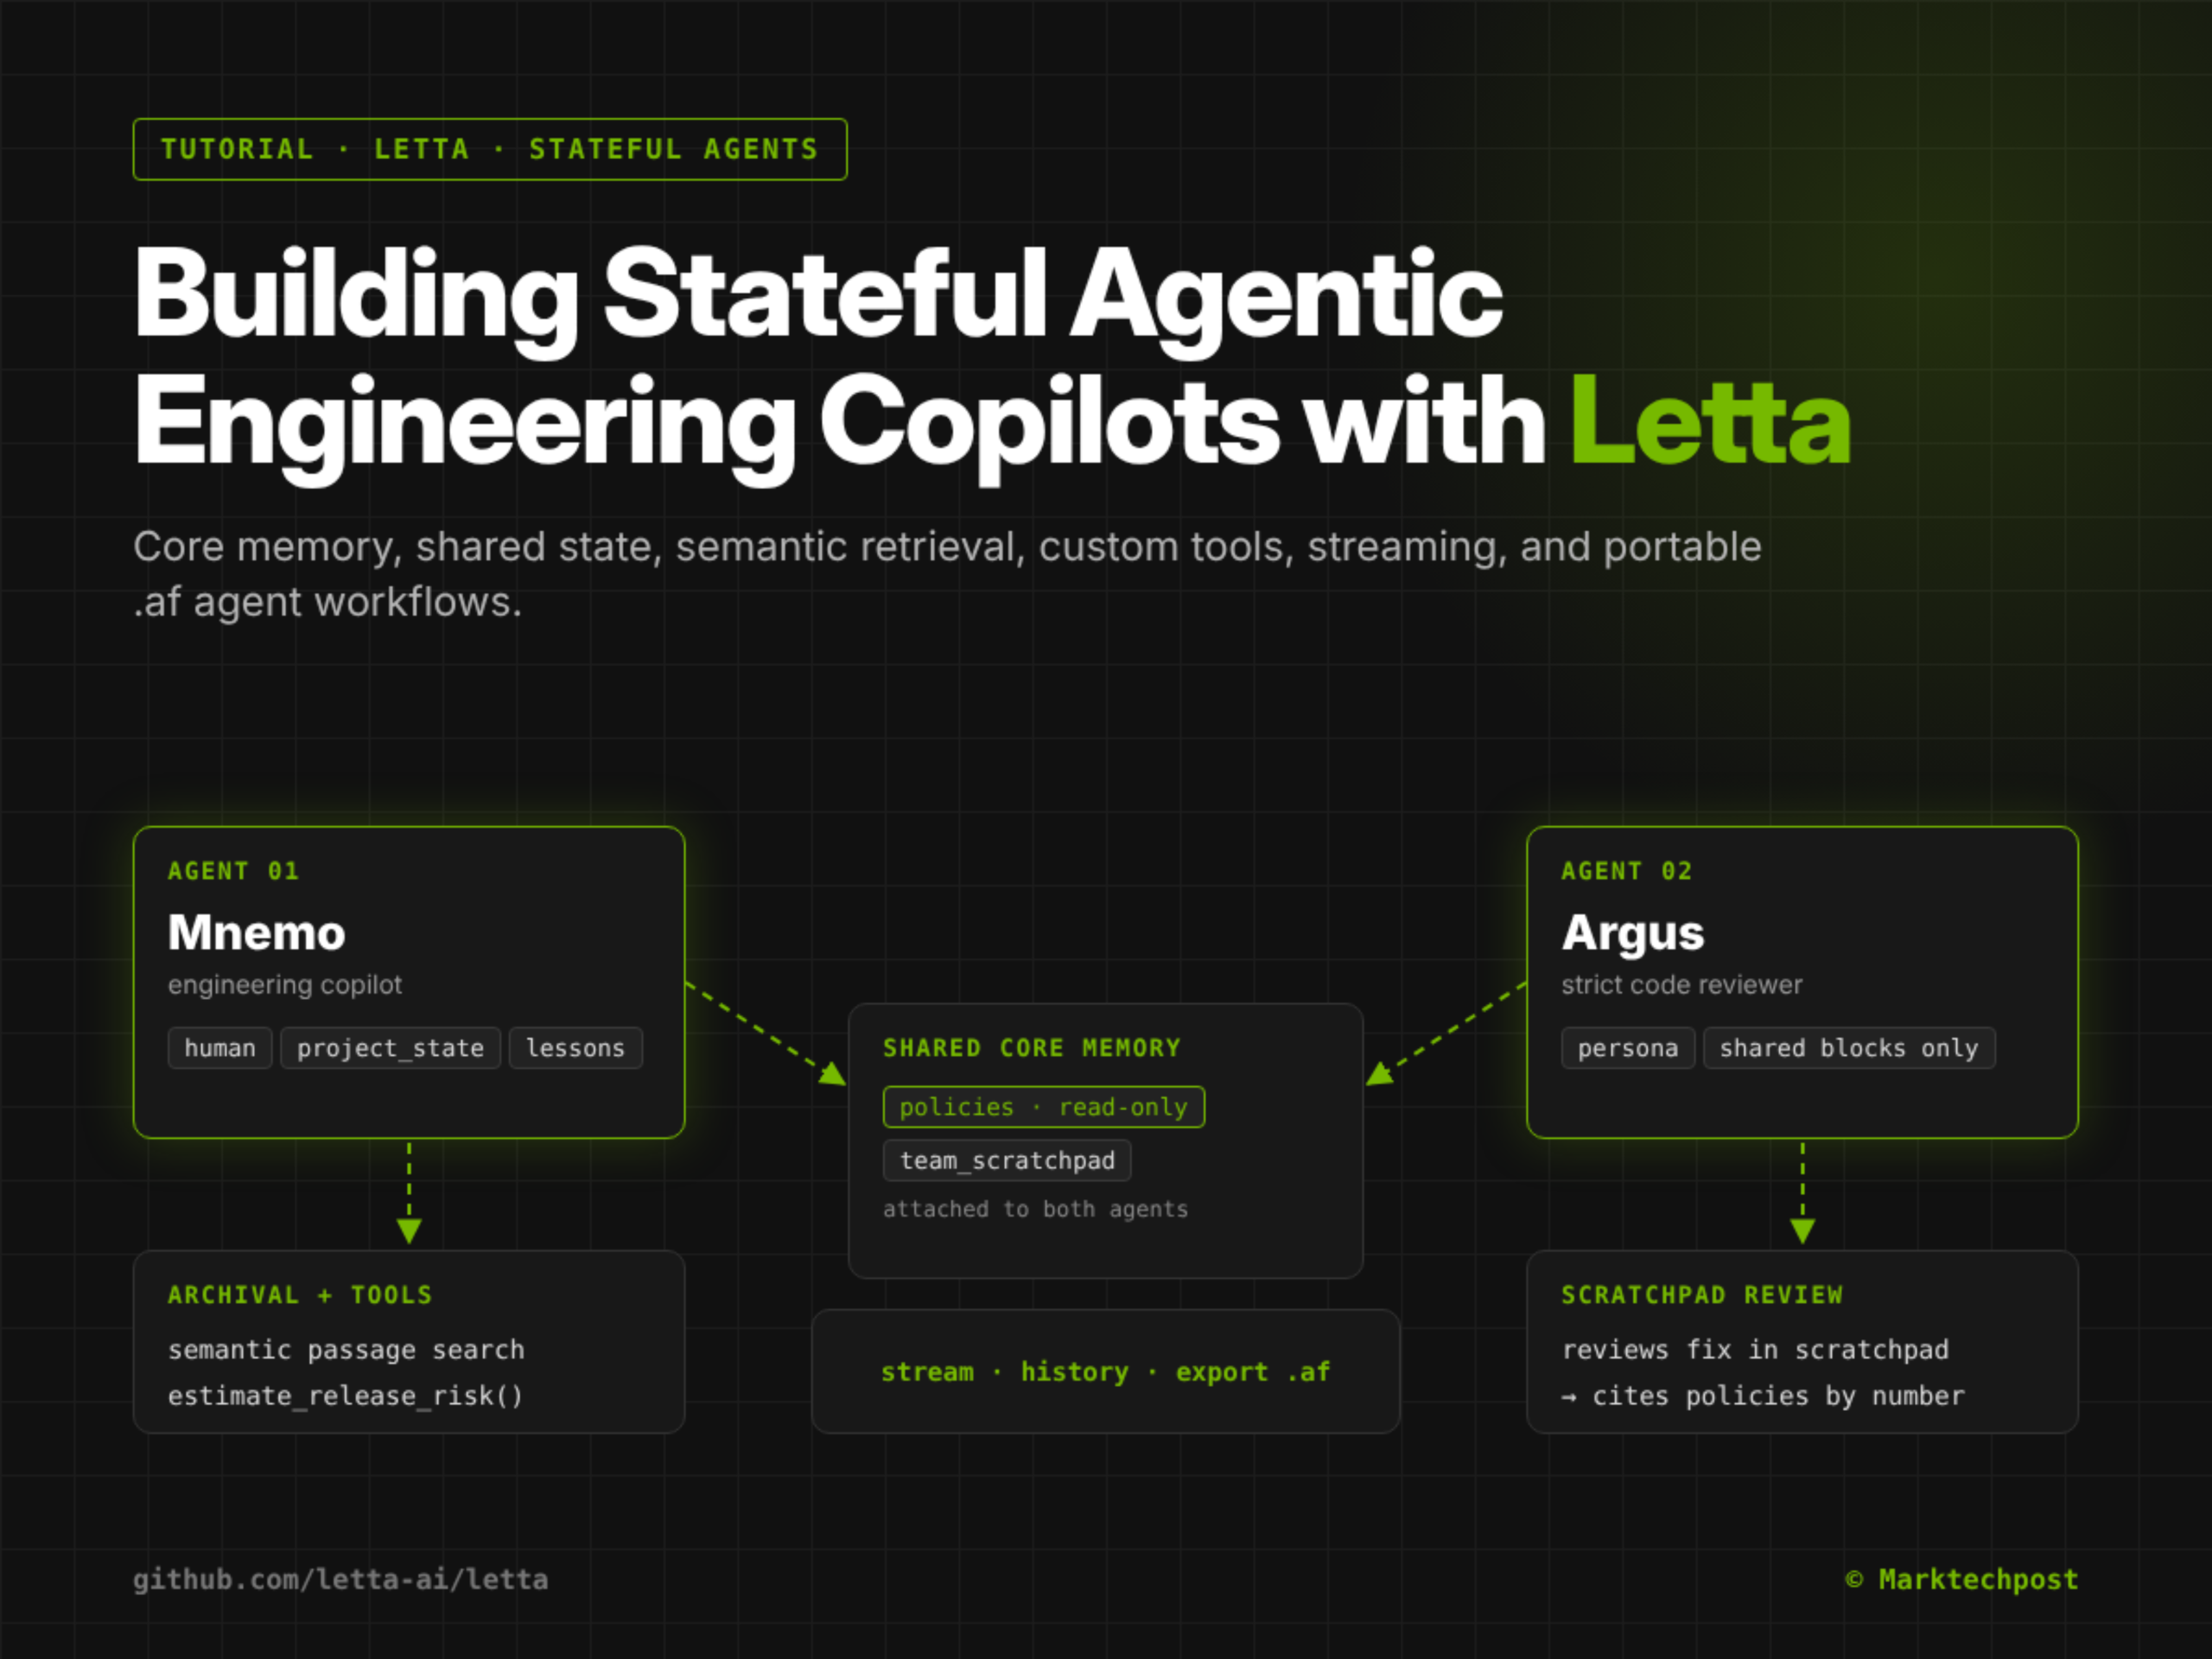
Letta platform releases a tutorial on building stateful engineering collaborators: supporting core memory, shared state, and portable workflows.

MarkTechPost published a tutorial on October 24, 2026, detailing how to build an agentic copilot with persistent state using the Letta framework. The guide covers capabilities such as verifiable core memory, multi-agent shared memory, semantic retrieval of archived knowledge, custom Python tool integration, streaming responses, and .agent format (.af) export. The content serves as a technical practice guide and does not provide performance metrics, security audits, or production‑environment validation.

Stateful Agentic Engineering Copilots with Letta: Core Memory, Shared State, Semantic Retrieval, Custom Tools, Streaming, and Portable Agent Workflows
Timeline and related coverage

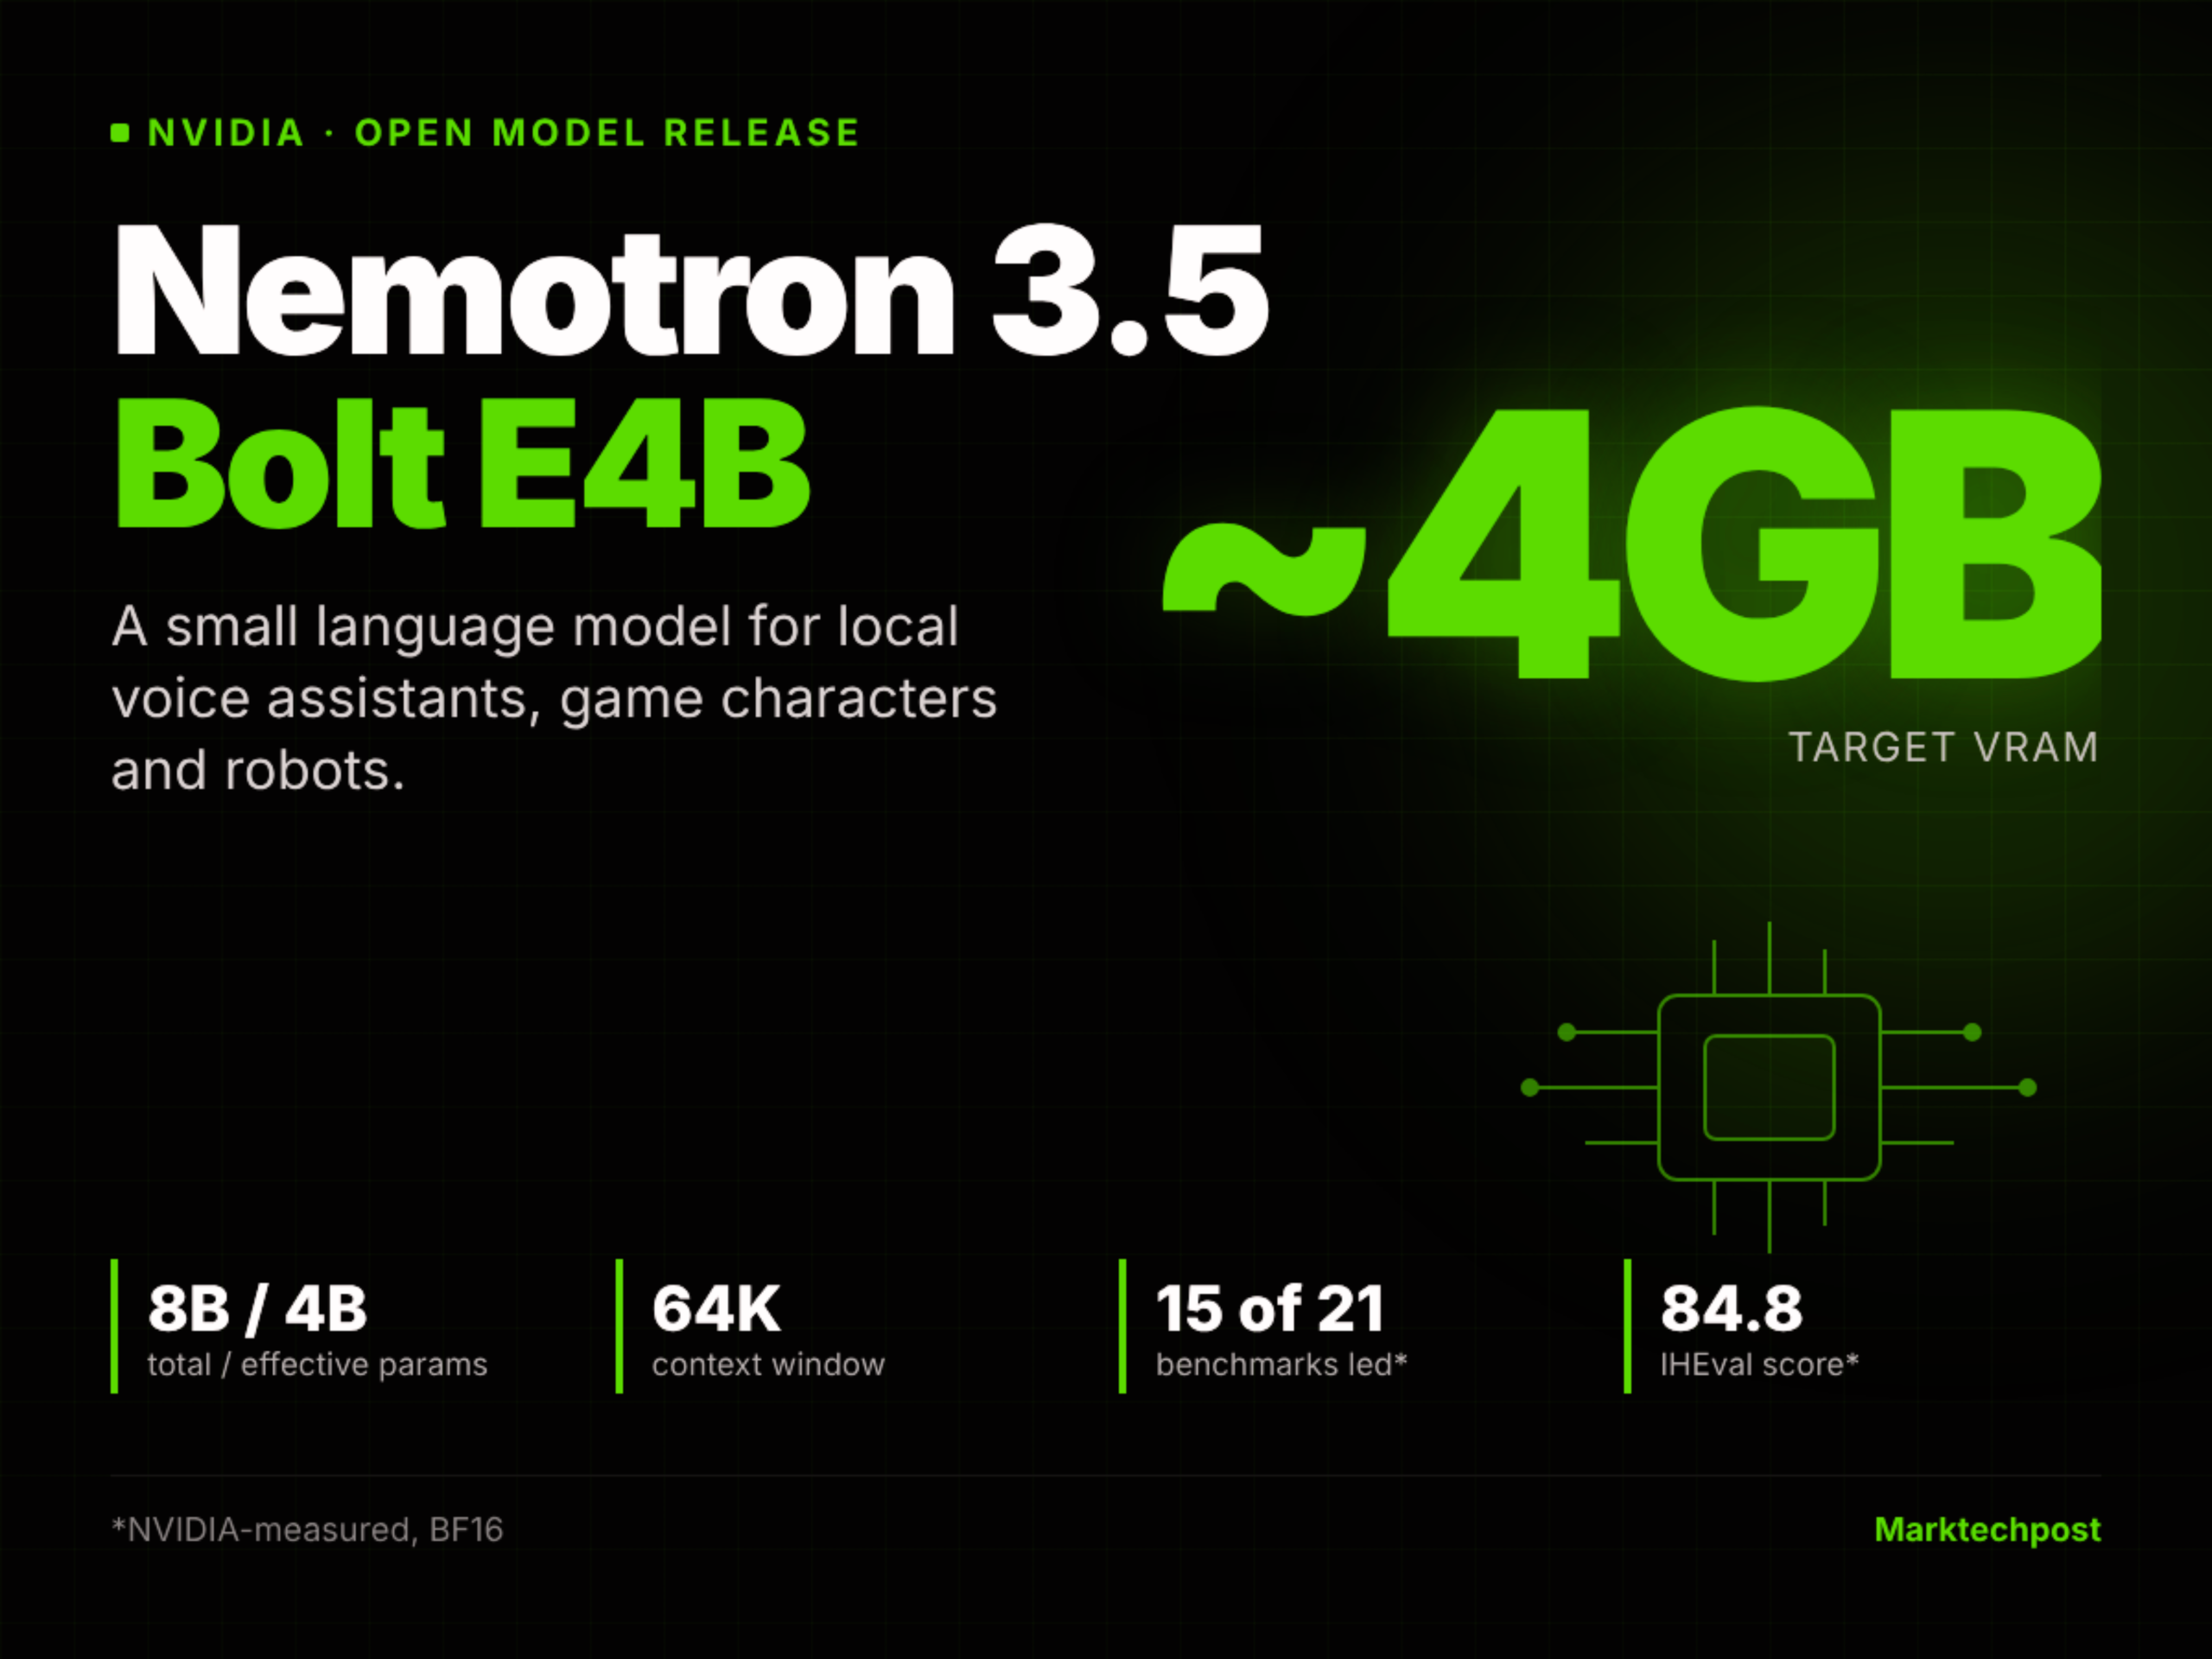
NVIDIA has released the open-source small language model Nemotron 3.5 Bolt E4B 4GB, optimized for on-device voice assistants, game NPCs, and robots.

NVIDIA, leveraging Google’s Gemma 4 E4B model and employing only reinforcement learning (RL) for post-training, has launched Nemotron 3.5 Bolt E4B 4GB—a small open-source language model with 8B total parameters, 4B effective parameters, and a 64K context window. It is designed to run on edge devices such as RTX and Jetson with approximately 4GB of VRAM, supporting multi-turn tool calls and low-latency voice interaction.

NVIDIA Releases Nemotron 3.5 Bolt E4B 4GB: An Open Small Language Model for Local Voice Agents, Game Characters and Robots
Timeline and related coverage

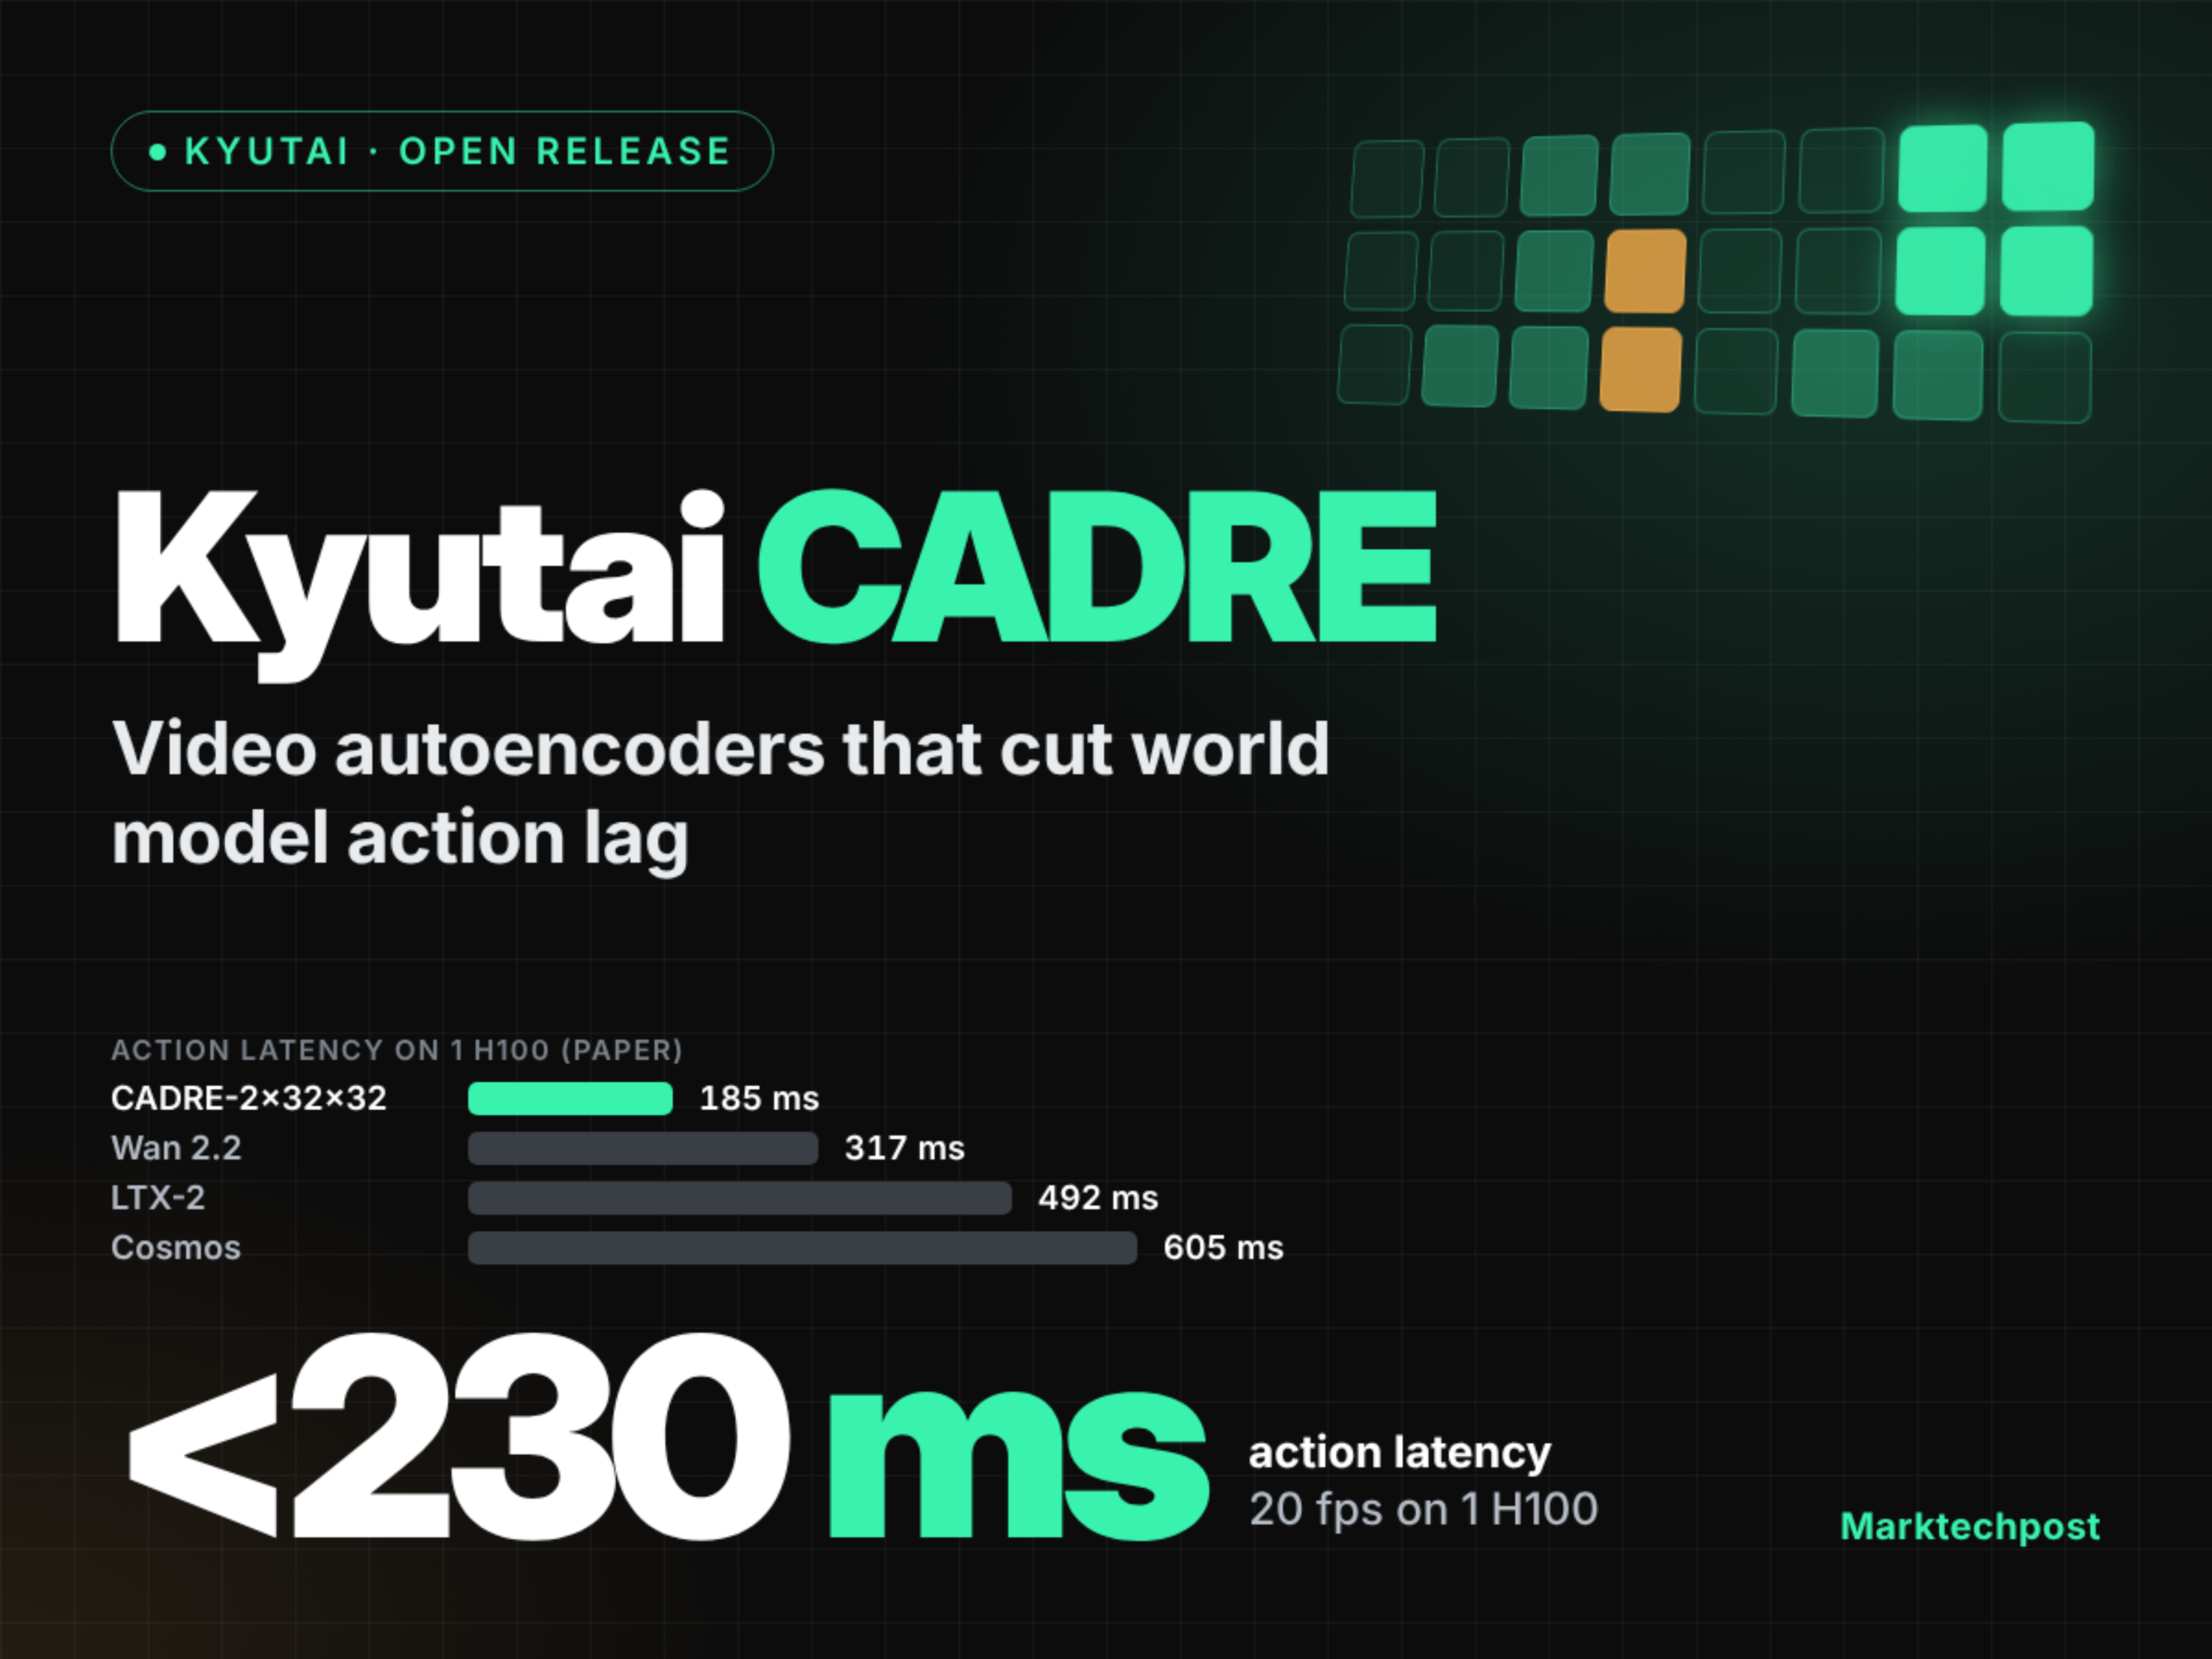
Kyutai releases the CADRE video autoencoder family: designed for interactive world models, with end-to-end action latency reduced to below 230 milliseconds.

On October 23, 2026, Kyutai unveiled CADRE—a family of seven open-source causal diffusion-based video autoencoders designed to reduce action latency in world models. On a single H100 GPU, measured response latency was as low as 185 ms, with inference throughput reaching 23.4 fps, and the scene FVD metric dropping to 162.6 (compared to 599.7 for Wan 2.2). However, in robotic manipulation tasks, its action following rate (ARR) lagged behind both Wan 2.2 and Cosmos.

Kyutai CADRE: Video Autoencoders That Cut World Model Lag Below 230 ms
Timeline and related coverage

Block releases its new voice AI model, Dessa: trained entirely on real-world conversations, with a slightly awkward conversational style.

Jack Dorsey’s company, Block, announced the launch of an end-to-end voice AI model called Dessa, claiming it was trained entirely from scratch using only human speech dialogue data. The official demonstration samples exhibited a mix of naturalness and awkwardness—for example, mistakenly addressing a user as “Ronaldo”—highlighting its anthropomorphic yet still immature conversational capabilities.

Timeline and related coverage

AWS CDK builds reusable constructs to resolve the blocking issue during SageMaker endpoint scaling updates.

When a SageMaker real-time AI endpoint has Application Auto Scaling enabled, attempting to update its configuration—such as instance type or count—directly via AWS CDK or CloudFormation will fail. This paper proposes a CDK construct based on custom resources that leverages strict dependency orchestration to achieve atomic updates of both the endpoint’s configuration and its scaling policies, eliminating the need for manual intervention.

Timeline and related coverage

Amazon QuickSight’s layered maps now support GeoJSON point and line features, enabling the visualization of locations and routes together.

Amazon QuickSight’s layered maps now support the GeoJSON formats for Point and LineString geometries, enabling users to overlay store locations, delivery routes, or flight trajectories on the same map. This capability requires no third-party services, but it does demand that GeoJSON files adhere to the proper structure, with matching keys and static updates.

Timeline and related coverage

Black October: A Comprehensive Overview of the AI-Driven Cybersecurity Crisis—From Its Peak to Defensive Response

Around October 21–22, 2026, over a span of approximately 48 hours, more than a dozen high‑severity AI‑related vulnerabilities and intrusion incidents were reported worldwide, including PHP2Shell, GitLab RCE (CVSS 10), NGINX/HTTP/3 DoS, LiteLLM password theft, eMudhra CA key leakage, and Quest Diagnostics medical data exposure. State actors such as Storm‑0940 leveraged open‑source intelligent penetration‑testing frameworks like ARTEX to launch large‑scale attacks. Concurrently, AI security defense systems were rapidly being developed, encompassing formal verification, open‑source patching agents, standardization of agent capabilities, and hardware‑level optimizations.

Timeline and related coverage

inDrive, in partnership with Pony.ai and NVIDIA, plans to launch autonomous taxi trials in Astana, the capital of Kazakhstan, in the first half of 2027.

Ride-hailing platform inDrive has signed memorandums of understanding with Pony.ai and NVIDIA, planning to launch Gen-7 autonomous taxi trials in Astana, the capital of Kazakhstan, in the first half of 2027. Initially, these vehicles will be equipped with safety drivers, with the ultimate goal of achieving fully driverless operation; NVIDIA will provide AI technology support, including the Hyperion platform and the Halos safety system.

Timeline and related coverage

1Password launches the “AI Proxy Login” feature: AI can log in to accounts on behalf of users, without ever accessing their passwords.

On October 22, 2026, 1Password launched a new platform called “1Password for Agents,” which allows users to authorize AI agents—such as Claude Duet, ChatGPT Work, Grok Bot, and others—to log into their personal accounts on their behalf. The agents themselves cannot access, store, or view the original passwords; the entire process relies on digital identity verification, real-time user confirmation, and automatic password filling by the password manager.

Timeline and related coverage

Canva has launched its first in-house image-generation model, Canva Craft, which is now available to all users.

Canva has officially launched its first in-house image-generation model, Canva Craft, which employs a two-stage generative architecture, supports 2K resolution and output in 30 aspect ratios, and emphasizes text readability and layer editability. The model was trained on millions of human-designed templates within the platform and has already been integrated into Dream Lab and the API; going forward, it will be accessible via MCP to third-party chatbots such as ChatGPT and Gemini.

Timeline and related coverage

OpenAI officially launches the Decisions API decision-making model, directly competing with TypeSafe Jev.

OpenAI will make the Decisions API available to all customers around October 22, 2026. This model is rebuilt on top of ChatGPT Luna and emphasizes millisecond-level low latency and cost-effective inference, with advantages in multimodal tasks such as image understanding. Currently, it lags behind competitors like the latest Jev and D1 Ultra in mainstream decision-making model benchmarks, but has already been adopted in real-world testing by companies including Box, Datadog, and Speak.

Timeline and related coverage

Major upgrade to Amazon Polly’s generative engine: 14 new voices added, and for the first time, support for Hindi and Finnish generative speech, with zero-code migration.

Amazon Polly’s generative engine has undergone a major upgrade, significantly enhancing speech naturalness, accuracy, and emotional expressiveness, while supporting low-latency streaming synthesis. Fourteen new generative voices have been added, covering nine regions, and for the first time, generative voices in Hindi (Arjun, Kiara) and Finnish (Suvi) are universally available. The entire update is a seamless, drop-in replacement, requiring no changes to API calls or code.

Timeline and related coverage