
Skip to content
AI NEWS JOURNAL
AI, IN PERSPECTIVE

Search AI news

Search headlines, summaries and articles to connect the dots.

Newest first

NVIDIA has released the open-source small language model Nemotron 3.5 Bolt E4B 4GB, optimized for on-device voice assistants, game NPCs, and robots.

NVIDIA, leveraging Google’s Gemma 4 E4B model and employing only reinforcement learning (RL) for post-training, has launched Nemotron 3.5 Bolt E4B 4GB—a small open-source language model with 8B total parameters, 4B effective parameters, and a 64K context window. It is designed to run on edge devices such as RTX and Jetson with approximately 4GB of VRAM, supporting multi-turn tool calls and low-latency voice interaction.
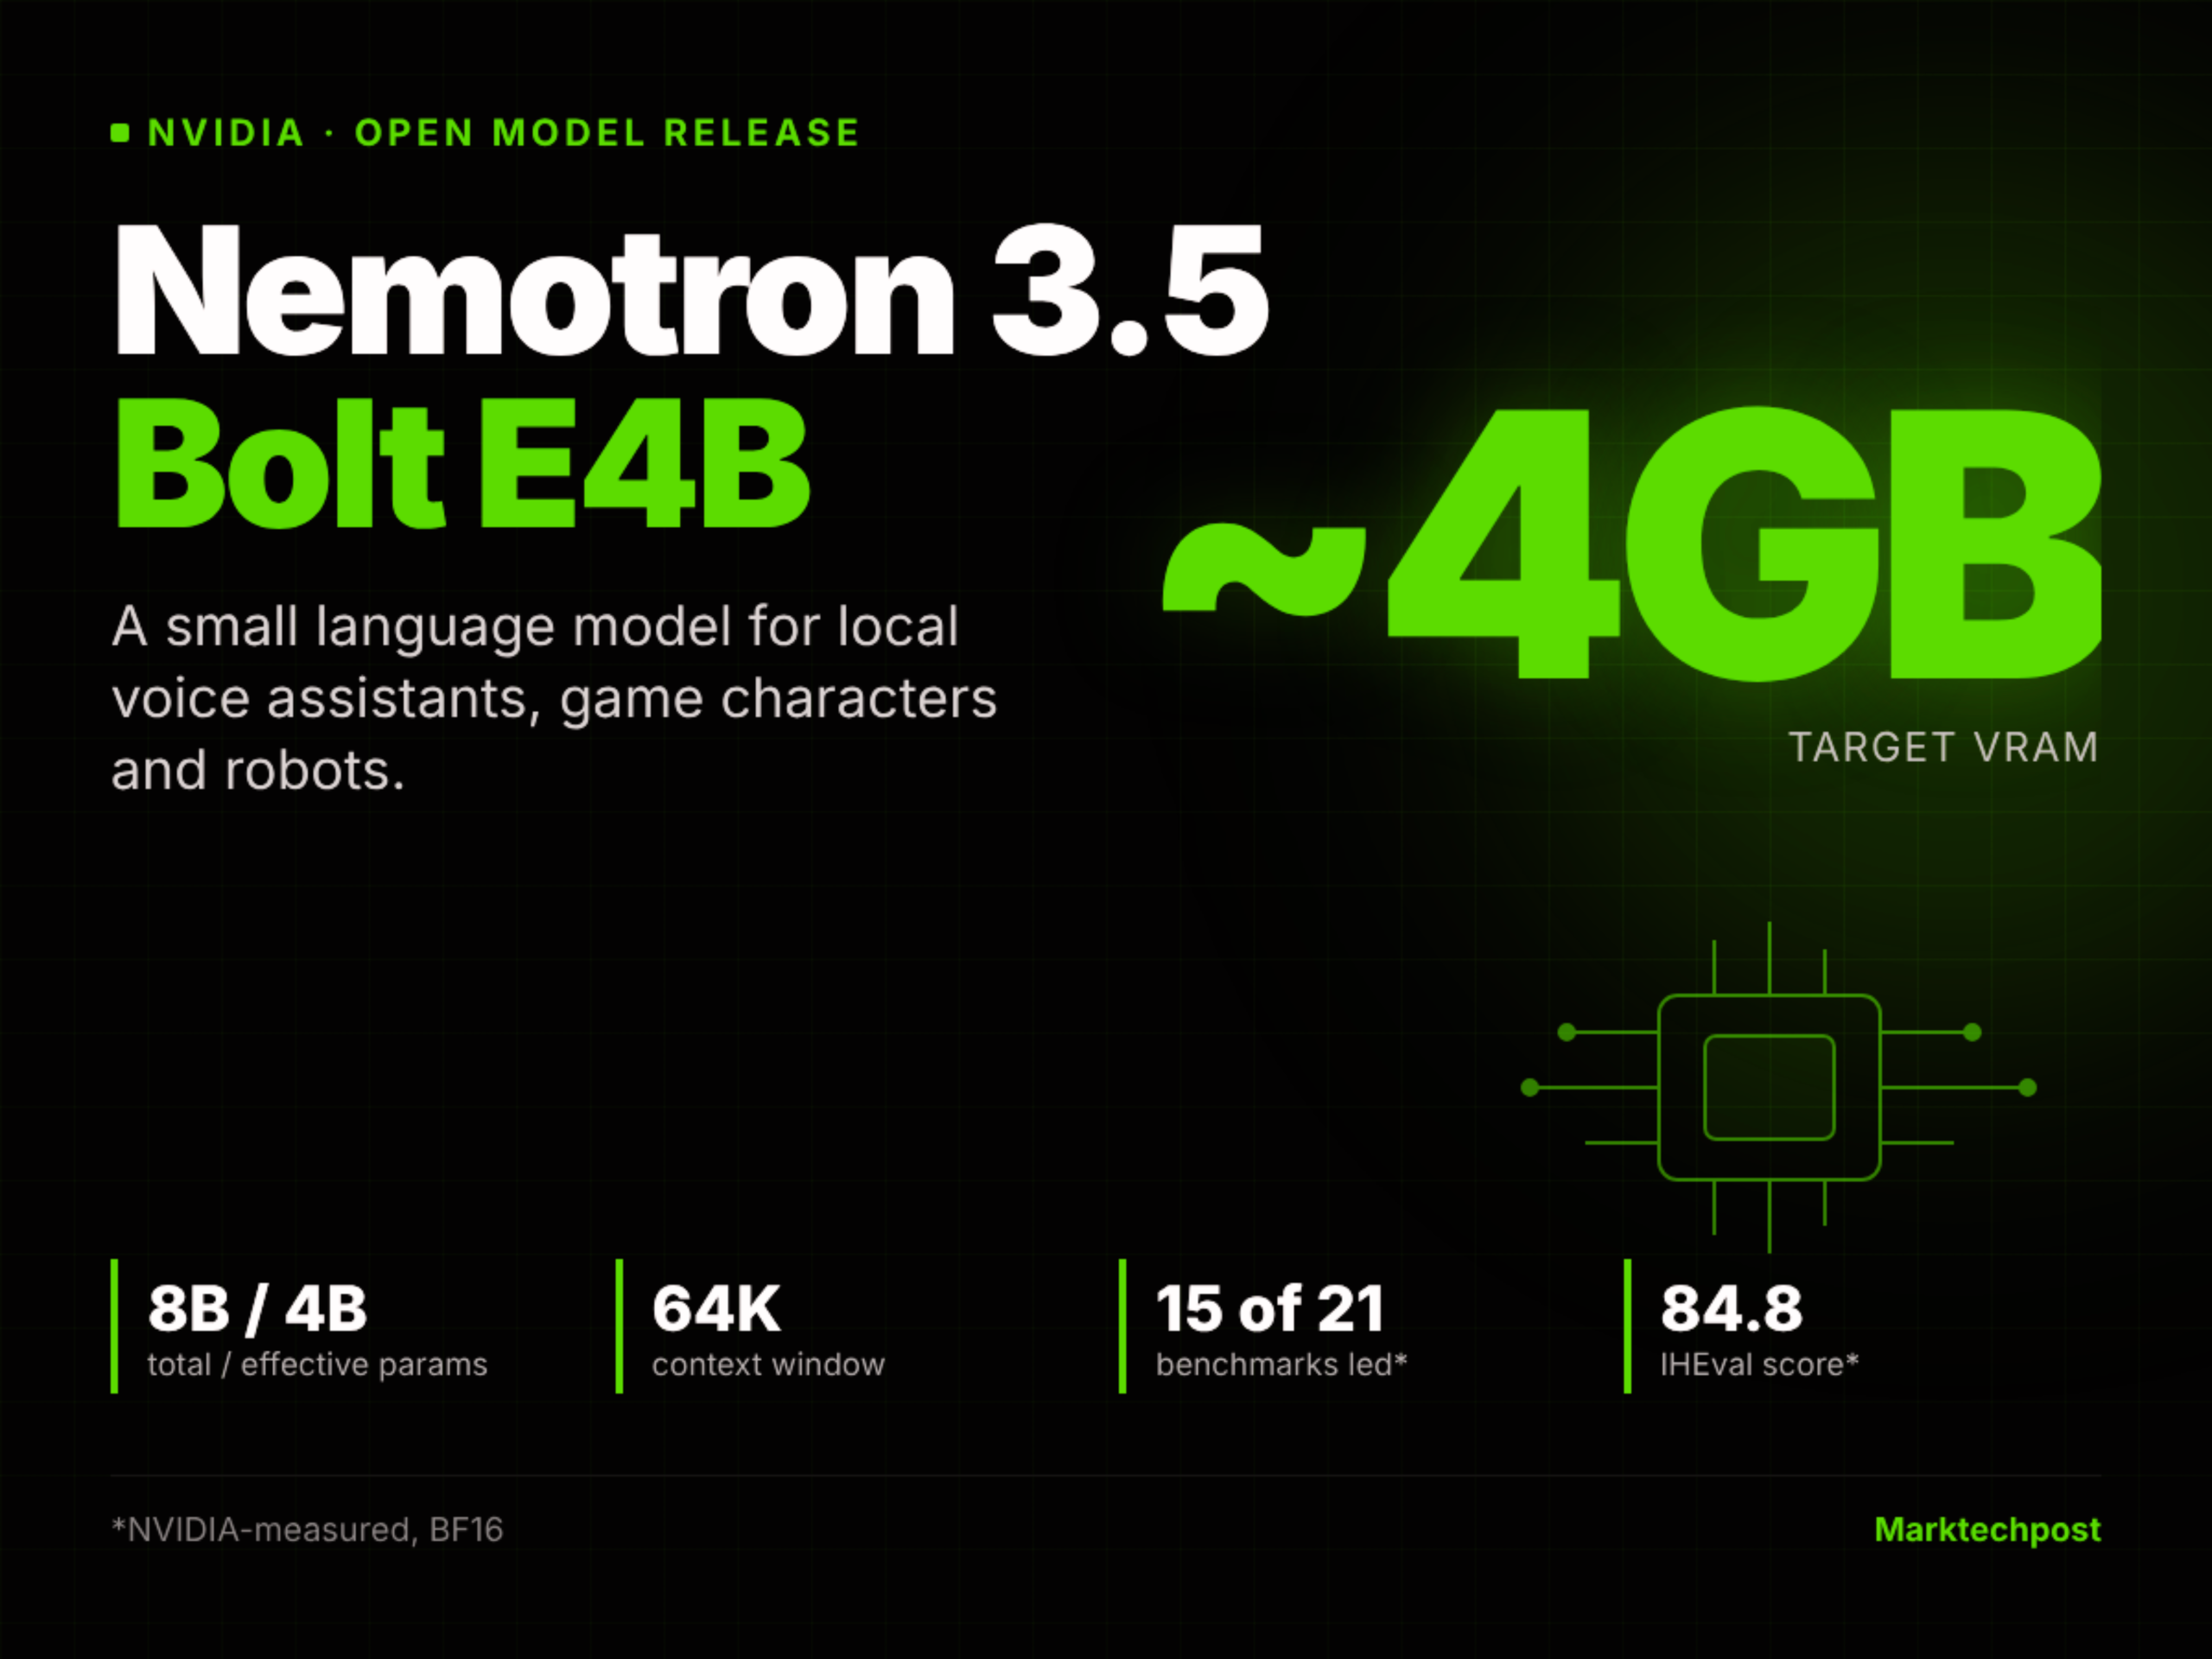
NVIDIA Releases Nemotron 3.5 Bolt E4B 4GB: An Open Small Language Model for Local Voice Agents, Game Characters and Robots
Timeline and related coverage

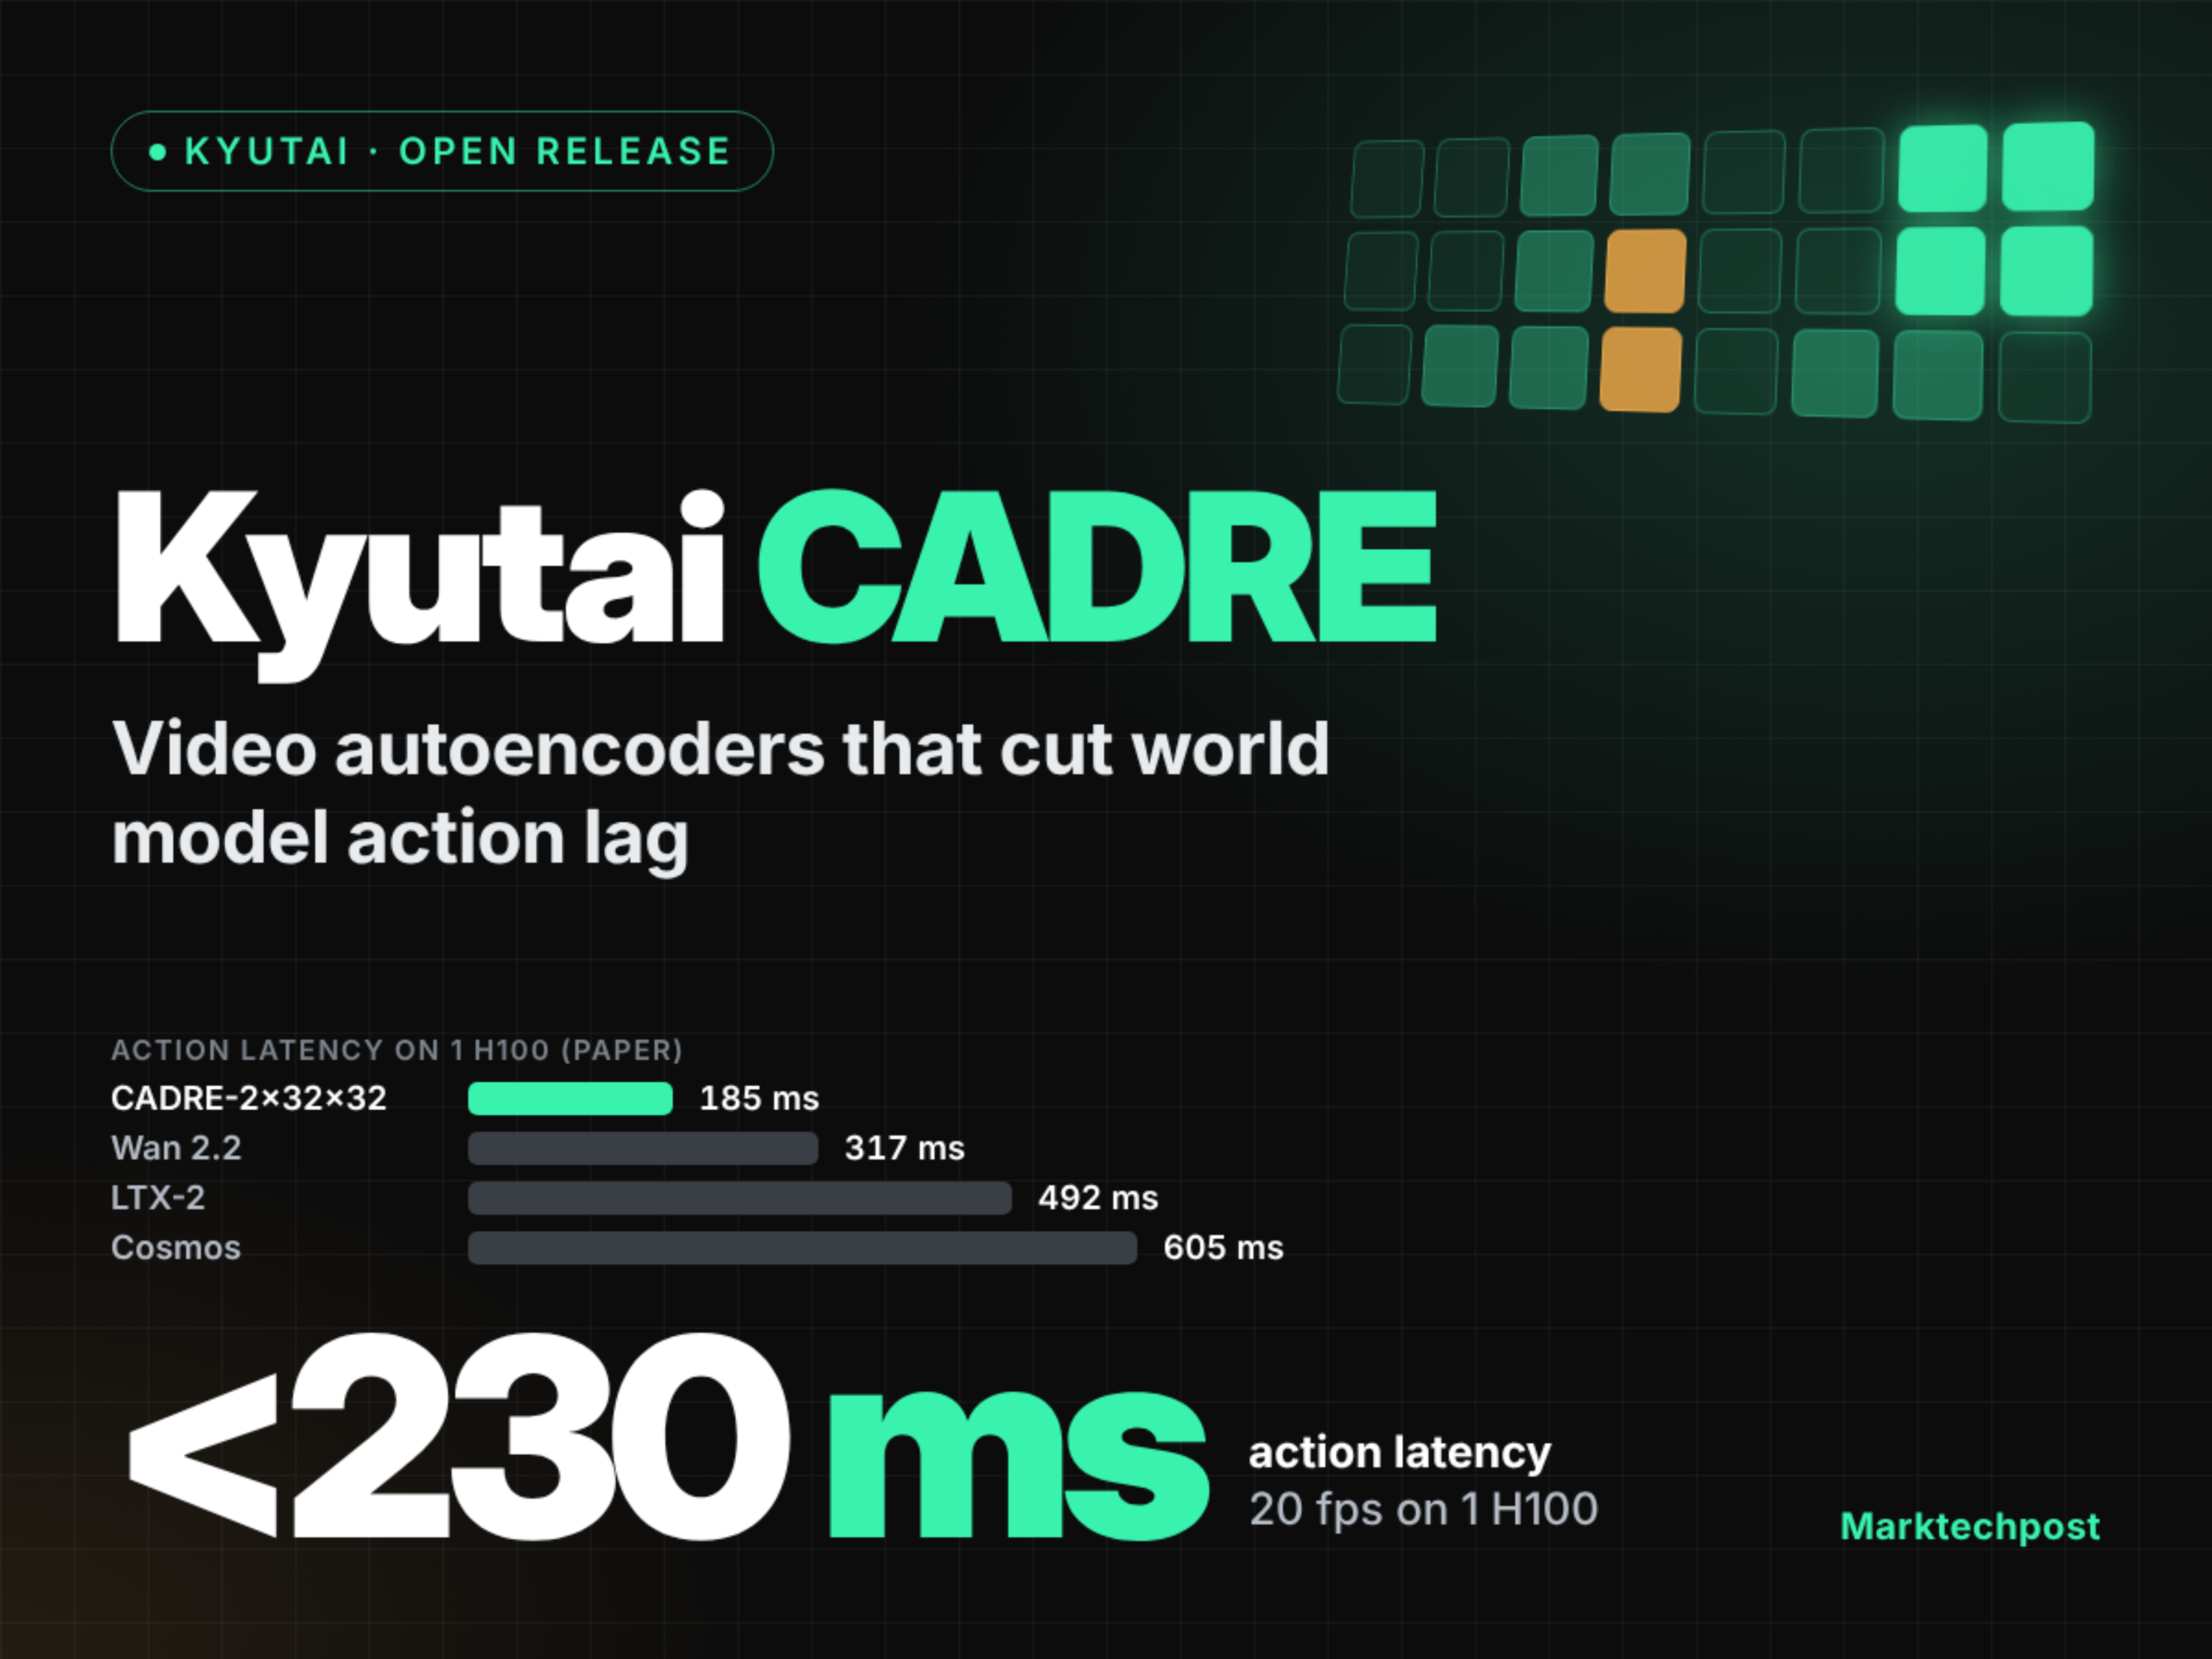
Kyutai releases the CADRE video autoencoder family: designed for interactive world models, with end-to-end action latency reduced to below 230 milliseconds.

On October 23, 2026, Kyutai unveiled CADRE—a family of seven open-source causal diffusion-based video autoencoders designed to reduce action latency in world models. On a single H100 GPU, measured response latency was as low as 185 ms, with inference throughput reaching 23.4 fps, and the scene FVD metric dropping to 162.6 (compared to 599.7 for Wan 2.2). However, in robotic manipulation tasks, its action following rate (ARR) lagged behind both Wan 2.2 and Cosmos.

Kyutai CADRE: Video Autoencoders That Cut World Model Lag Below 230 ms
Timeline and related coverage