
NVIDIA RTX Spark Powers Neural Rendering and AI Characters in Games
NVIDIA RTX Spark is a new Windows PC platform for AI development, creation, and gaming in slim laptops and compact desktops. Powered by an NVIDIA Blackwell RTX...
Explore the complete news stream by source, topic and date.
NVIDIA RTX Spark is a new Windows PC platform for AI development, creation, and gaming in slim laptops and compact desktops. Powered by an NVIDIA Blackwell RTX...
metal : add GGML_OP_TOP_K_MASK (#31230) * metal : add GGML_OP_TOP_K_MASK Port the fused top-k mask from the CUDA backend: a grid-stride kernel fills the output with -inf, then one threadgroup per row copies the mask values of the kept cells over it. Function constants drop the score, blocks and extra paths that a given graph does not use. Assisted-by: dsh:llama.cpp/ggml-org/Qwen3.8-Flash-Next-GGUF (MacBook, M5 Max, 128GB) * metal : clean up top-k mask kernel formatting Assisted-by: dsh:llama.cpp/ggml-org/Qwen3.8-Flash-Next-GGUF (MacBook, M5 Max, 128GB) **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b11927/llama-b11927-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](
Simplismart says its annualized revenue run rate has grown 14-fold in six months, with the U.S. accounting for more than half its revenue.
glm5-next : QSA without kq_mask (+ DSA) (#31009) * glm5-next : QSA without kq_mask * DSA: dsa top-k mask change tested with layers 0,3 of DeepSeek-V3.2 **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b11926/llama-b11926-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel (x64)](https://github.com/ggml-org/llama.cpp/releases/download/b11926/llama-b11926-bin-macos-x64.tar.gz) - [iOS XCFramework](https://github.com/ggml-org/llama.cpp/releases/download/b11926/llama-b11926-xcframework.zip) **Linux:** - [Ubuntu x64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b11926/llama-b11926-bin-ubuntu-x64.t
On October 27, Rokid launched the AI glasses Rokid Glasses 2, the full-color AI glasses Rokid Color, and the interactive ring Rokid Ring.
Index implementation plus ETF authorization have provided Hong Kong‑listed AI and semiconductor stocks with new allocation tools and a fresh source of capital.
During the 2026 Changsha · 1024 Programmers’ Day event, the CEIC Consumer Electronics Innovation Conference and CSDN joined forces in Shenzhen to present a cutting-edge tech extravaganza for developers. As Yang Tao, Executive Deputy Director of the CEIC Organizing Committee, noted in an interview: “Ultimately, every experience innovation in the consumer electronics field is brought to life by the code written by our programmers.” At this pivotal moment in technological advancement, the evolution has moved from plain hand-written code to leveraging intelligent agents (Agents) and powerful on-device APs...
According to a report by The Verge on October 27, 2026, communities across the United States have mounted widespread opposition to the large-scale construction of data centers and the soaring costs of associated infrastructure, with this issue deeply entangled in numerous congressional and gubernatorial races. Tech capital is accelerating its entry into the fray: the super PAC “Leading the Future,” backed by Marc Andreessen and Greg Brockman, has already spent $45 million within a year, while “Public First Action,” supported by Anthropic, has also joined the effort.
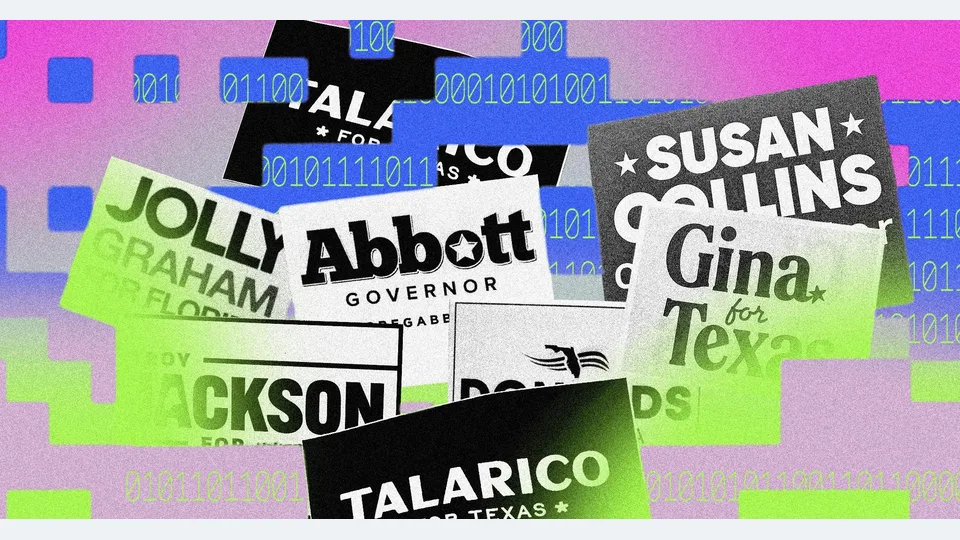
Why it matters:The source of the material is clearly identified (The Verge), and the publication date matches the current system time (2026-10-27). The content focuses on verifiable public policies and electoral developments, including specific entities, monetary amounts, timelines, and organizational relationships, thereby meeting the requirements for timeliness and factual grounding.
ci : use ccache depend mode for ROCm release builds (#31231) **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b11925/llama-b11925-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel (x64)](https://github.com/ggml-org/llama.cpp/releases/download/b11925/llama-b11925-bin-macos-x64.tar.gz) - [iOS XCFramework](https://github.com/ggml-org/llama.cpp/releases/download/b11925/llama-b11925-xcframework.zip) **Linux:** - [Ubuntu x64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b11925/llama-b11925-bin-ubuntu-x64.tar.gz) - [Ubuntu arm64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b1192
ggml : relax scale to non-contiguous views (#31146) * ggml : relax scale to non-contiguous views SCALE requires src0 to be 1D-contiguous. Relax this to dim-0 contiguity with arbitrary row strides (ggml_is_contiguous_rows), same as the unary ops in the Metal backend. - ggml: relax the assert in ggml_scale_impl - cpu: address src0 rows through their byte strides (f32, bf16) - cuda: stride-aware kernel, fastdiv row decomposition - metal: support bf16 scale (guarded unary instantiations) - sycl: keep the gate at contiguous, the kernel is flat f32 Add view variants to test_scale. Verified on CPU, Metal and CUDA. Assisted-by: dsh:llama.cpp/ggml-org/Qwen3.8-Flash-Next-GGUF (RTX 5090 32GB, DDR5 128GB) * cuda : skip the softcap fusion on non-contiguous views The fused softcap kernel reads src and w
tests : fix multi-seq split replay and partial-state cases for trained models (#31216) * tests : fix multi-seq split replay against trained models The rollback snapshot is captured by the graph that decoded the rolled-back tail, while the reference context decodes the same prefix with different batch shapes. The two states differ in the last bits and trained models amplify the difference with every replayed token. Compare only the first replayed token of each seq, then restore the rollback state into the reference context before the seq-1-only tail. Assisted-by: dsh:llama.cpp/ggml-org/Qwen3.8-Flash-Next-GGUF (MacBook, M5 Max, 128GB) * tests : require bit-exact seq-1 isolation in split replay The seq state save is not always bit-lossless - SWA-masked cells are not saved - so reload the rest
llama : remove obsolete n_pad from memory instances (#31200) Every caller passes n_pad = 1 and the only two users clamp it to 256. Drop the parameter, the members and the trivially true kv_size assert. Assisted-by: dsh:llama.cpp/ggml-org/Qwen3.8-Flash-Next-GGUF (MacBook, M5 Max, 128GB) **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b11921/llama-b11921-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel (x64)](https://github.com/ggml-org/llama.cpp/releases/download/b11921/llama-b11921-bin-macos-x64.tar.gz) - [iOS XCFramework](https://github.com/ggml-org/llama.cpp/releases/download/b11921/llama-b11921-xcfram
opencl: refine mul mat id -1 index (#31170) Assisted-by: Codex **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b11919/llama-b11919-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel (x64)](https://github.com/ggml-org/llama.cpp/releases/download/b11919/llama-b11919-bin-macos-x64.tar.gz) - [iOS XCFramework](https://github.com/ggml-org/llama.cpp/releases/download/b11919/llama-b11919-xcframework.zip) **Linux:** - [Ubuntu x64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b11919/llama-b11919-bin-ubuntu-x64.tar.gz) - [Ubuntu arm64 (CPU)](https://github.com/ggml-org/llama.cpp/releases/download/b11
opencl: initial support for q3_k (#31172) * opencl: add q3_k AOS mv * opencl: add q3_k SOA mv and tiled mm * opencl: add q3_k noshuffle gemm/gemv for adreno * opencl: add q3_k dp4a gemm for adreno Co-authored-by: Hongqiang Wang * opencl: tune q3_k kernels for adreno Co-authored-by: Hongqiang Wang --------- Co-authored-by: Hongqiang Wang **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b11918/llama-b11918-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel (x64)](https://github.com/ggml-org/llama.cpp/releases/download/b11918/llama-b11918-bin-macos-x64.tar.gz) - [iOS XCFramework](https://github.com/ggml-org/ll
Unprecedented demand for bandwidth calls for bringing optics closer to silicon through a fundamental rethinking of the optical interconnect roadmap. The post The imec Report: Scaling Optical Interconnects For The AI Era appeared first on Semiconductor Engineering.
vLLM Semantic Router released d3-ultra, a 27B open-weight multimodal decision model. It reads text, images and video once, then returns probabilities for every answer, scoring 87.2 on the team’s SR-Text test. The post vLLM Semantic Router Releases d3-ultra: A 27B Open Multimodal Decision Model appeared first on MarkTechPost.

arXiv:2610.33275v1 Announce Type: new Abstract: Computational notebooks reserve a GPU for the whole session, yet the GPU computes only while a cell executes and sits idle otherwise. Serverless execution would release the GPU between cells, but reconstructing the accumulated notebook state on a fresh worker imposes substantial cost on every GPU cell. This paper presents LooseLeaf, a serverless GPU platform for interactive notebooks. LooseLeaf derives the state and import closures of each cell, the minimal variables and packages that the cell needs. Our analysis on 5,000 real-world notebooks shows that these closures are small, and user-cell editing leaves seconds to prepare them. LooseLeaf prepares a GPU worker with these closures while the user edits the cell. After execution, the worker s

arXiv:2610.33475v1 Announce Type: new Abstract: The widespread deployment of foundational Large Language Models (LLM) across cloud datacenters marks a fundamental paradigm shift from stateless deep learning toward distributed, memory-intensive generative workloads. However, serving massive foundation models under stringent Service Level Objectives (SLO) exposes critical physical and system bottlenecks. These challenges include the persistent High Bandwidth Memory (HBM) wall, operational asymmetry between compute-bound prefilling and memory-bandwidth-bound decoding, explosive Key-Value (KV) cache expansion, prohibitive serverless cold starts, and hardware reliability vulnerabilities. Existing literature reviews remain layer-siloed, decoupling low-level accelerator virtualization from cluste
arXiv:2610.33501v1 Announce Type: new Abstract: Large language model (LLM) serving relies on batching to improve inference throughput, but the key-value (KV) cache grows with sequence length and limits GPU-resident concurrency. CPU offloading can expand KV capacity using host memory, yet existing systems remain largely GPU-gated: CPU-resident requests make progress only when the GPU scheduler exposes suitable overlap opportunities. As a result, host memory and CPU compute cannot act as an independent serving resource, leading to bursty CPU-side progress and inflated tail inter-token latency (ITL) under load. We present DualPace, an LLM serving runtime that turns the host into an independently scheduled decode engine. DualPace separates scheduling authority across two engines: the GPU engin
hexagon: add GGML_HEXAGON_VTCM_SIZE (#31221) * hexagon: add GGML_HEXAGON_VTCM_MB and GGML_HEXAGON_NTHREADS caps Change-Id: Idffe1613c8db6f96aa842d43d1b2efaed45462a8 * hexagon: rename VTCM cap to GGML_HEXAGON_VTCM_SIZE, drop NTHREADS cap Change-Id: If4c5b9ce9fd6b725c3561421c2295d40599d012d * hexagon: make GGML_HEXAGON_VTCM_SIZE an override, accept K/M/G suffixes Change-Id: Ib8eea84c22f24e6d986b37f215e504b046478c2c **Website:** - **Attestations:** - **macOS/iOS:** - [macOS Apple Silicon (arm64)](https://github.com/ggml-org/llama.cpp/releases/download/b11913/llama-b11913-bin-macos-arm64.tar.gz) - macOS Apple Silicon (arm64, KleidiAI enabled) [DISABLED](https://github.com/ggml-org/llama.cpp/pull/23780) - [macOS Intel (x64)](https://github.com/ggml-org/llama.cpp/releases/download/b11913/llama-b